Prioritization research for longtermist philanthropy. Previously ailabwatch.org.
Zach Stein-Perlman
Karma: 13,194
Yes but be careful about “marginal person.”
We can talk about Lukas’s value on the margin, which is probably slightly less than total impact * Lukas’s share of the credit due to diminishing returns in the size of the field but that’s not obvious
We can talk about causing new people, who tend to add much less value than average, to join the field
The correct concept here is the former, I think, since we’re talking about trading off between money and work by great people.
I think the value of a year of the AI safety nonprofit ecosystem is ~50B times the value of a marginal dollar, so if one safety researcher is worth ~1/5K of the ecosystem (depends on the person!), that’s $50B/5K = $10M/year.
Strong disagree.
Re A and B, yep, what else are you supposed to do? Within the stuff you can’t evaluate well, there’s a bunch of people who say they have ideas, and most of them are wrong or grifters but maybe some are legit, it’s tough. Note that giving money to useless stuff and grifters is worse than lighting the money on fire.
Unfortunately you generally don’t get “observed performance” from your grants, or it’s a lot of work — it’s often no easier to evaluate a past grant than to evaluate an application.
I think LTF is sign-unclear—they’re cartoonishly evil but their execution is also sometimes cartoonish. I think you mean “if I ever think that LTF wasn’t cartoonishly evil.”
My view is that Eliezer and Paul have historically both said what they believe, and I interpret Ben as suggesting that Paul is secretly more doomy than he says but tones it down for status or something.
I am annoyed by how you suggest that only your subtribe says what it believes. You know how it would be silly to say “One of the top 3 things that has made Eliezer’s career has been writing a lot in public about this subject in a way that is rhetorically alarming”? I think your comment is similarly silly.
I think betting on big AI companies has negligible effect on the rate of AI progress.
Great question. Unfortunately I don’t know and I’m certainly not going to be able to persuade anyone now. I hope some collaborators will write about this, although they probably won’t publish. Here are some lower bounds: SALP, VARA, SMH calls, TAI-thesis-stocks with leverage. (This is not in the squiggle.)
Most Anthropic equity that will ever be used for longtermist philanthropy should be sold ASAP and reinvested
Kindness to Kin is an underrated 2021 Yudkowsky short story. I think of it in a related genre to The Fable of the Dragon‑Tyrant and Solstice.
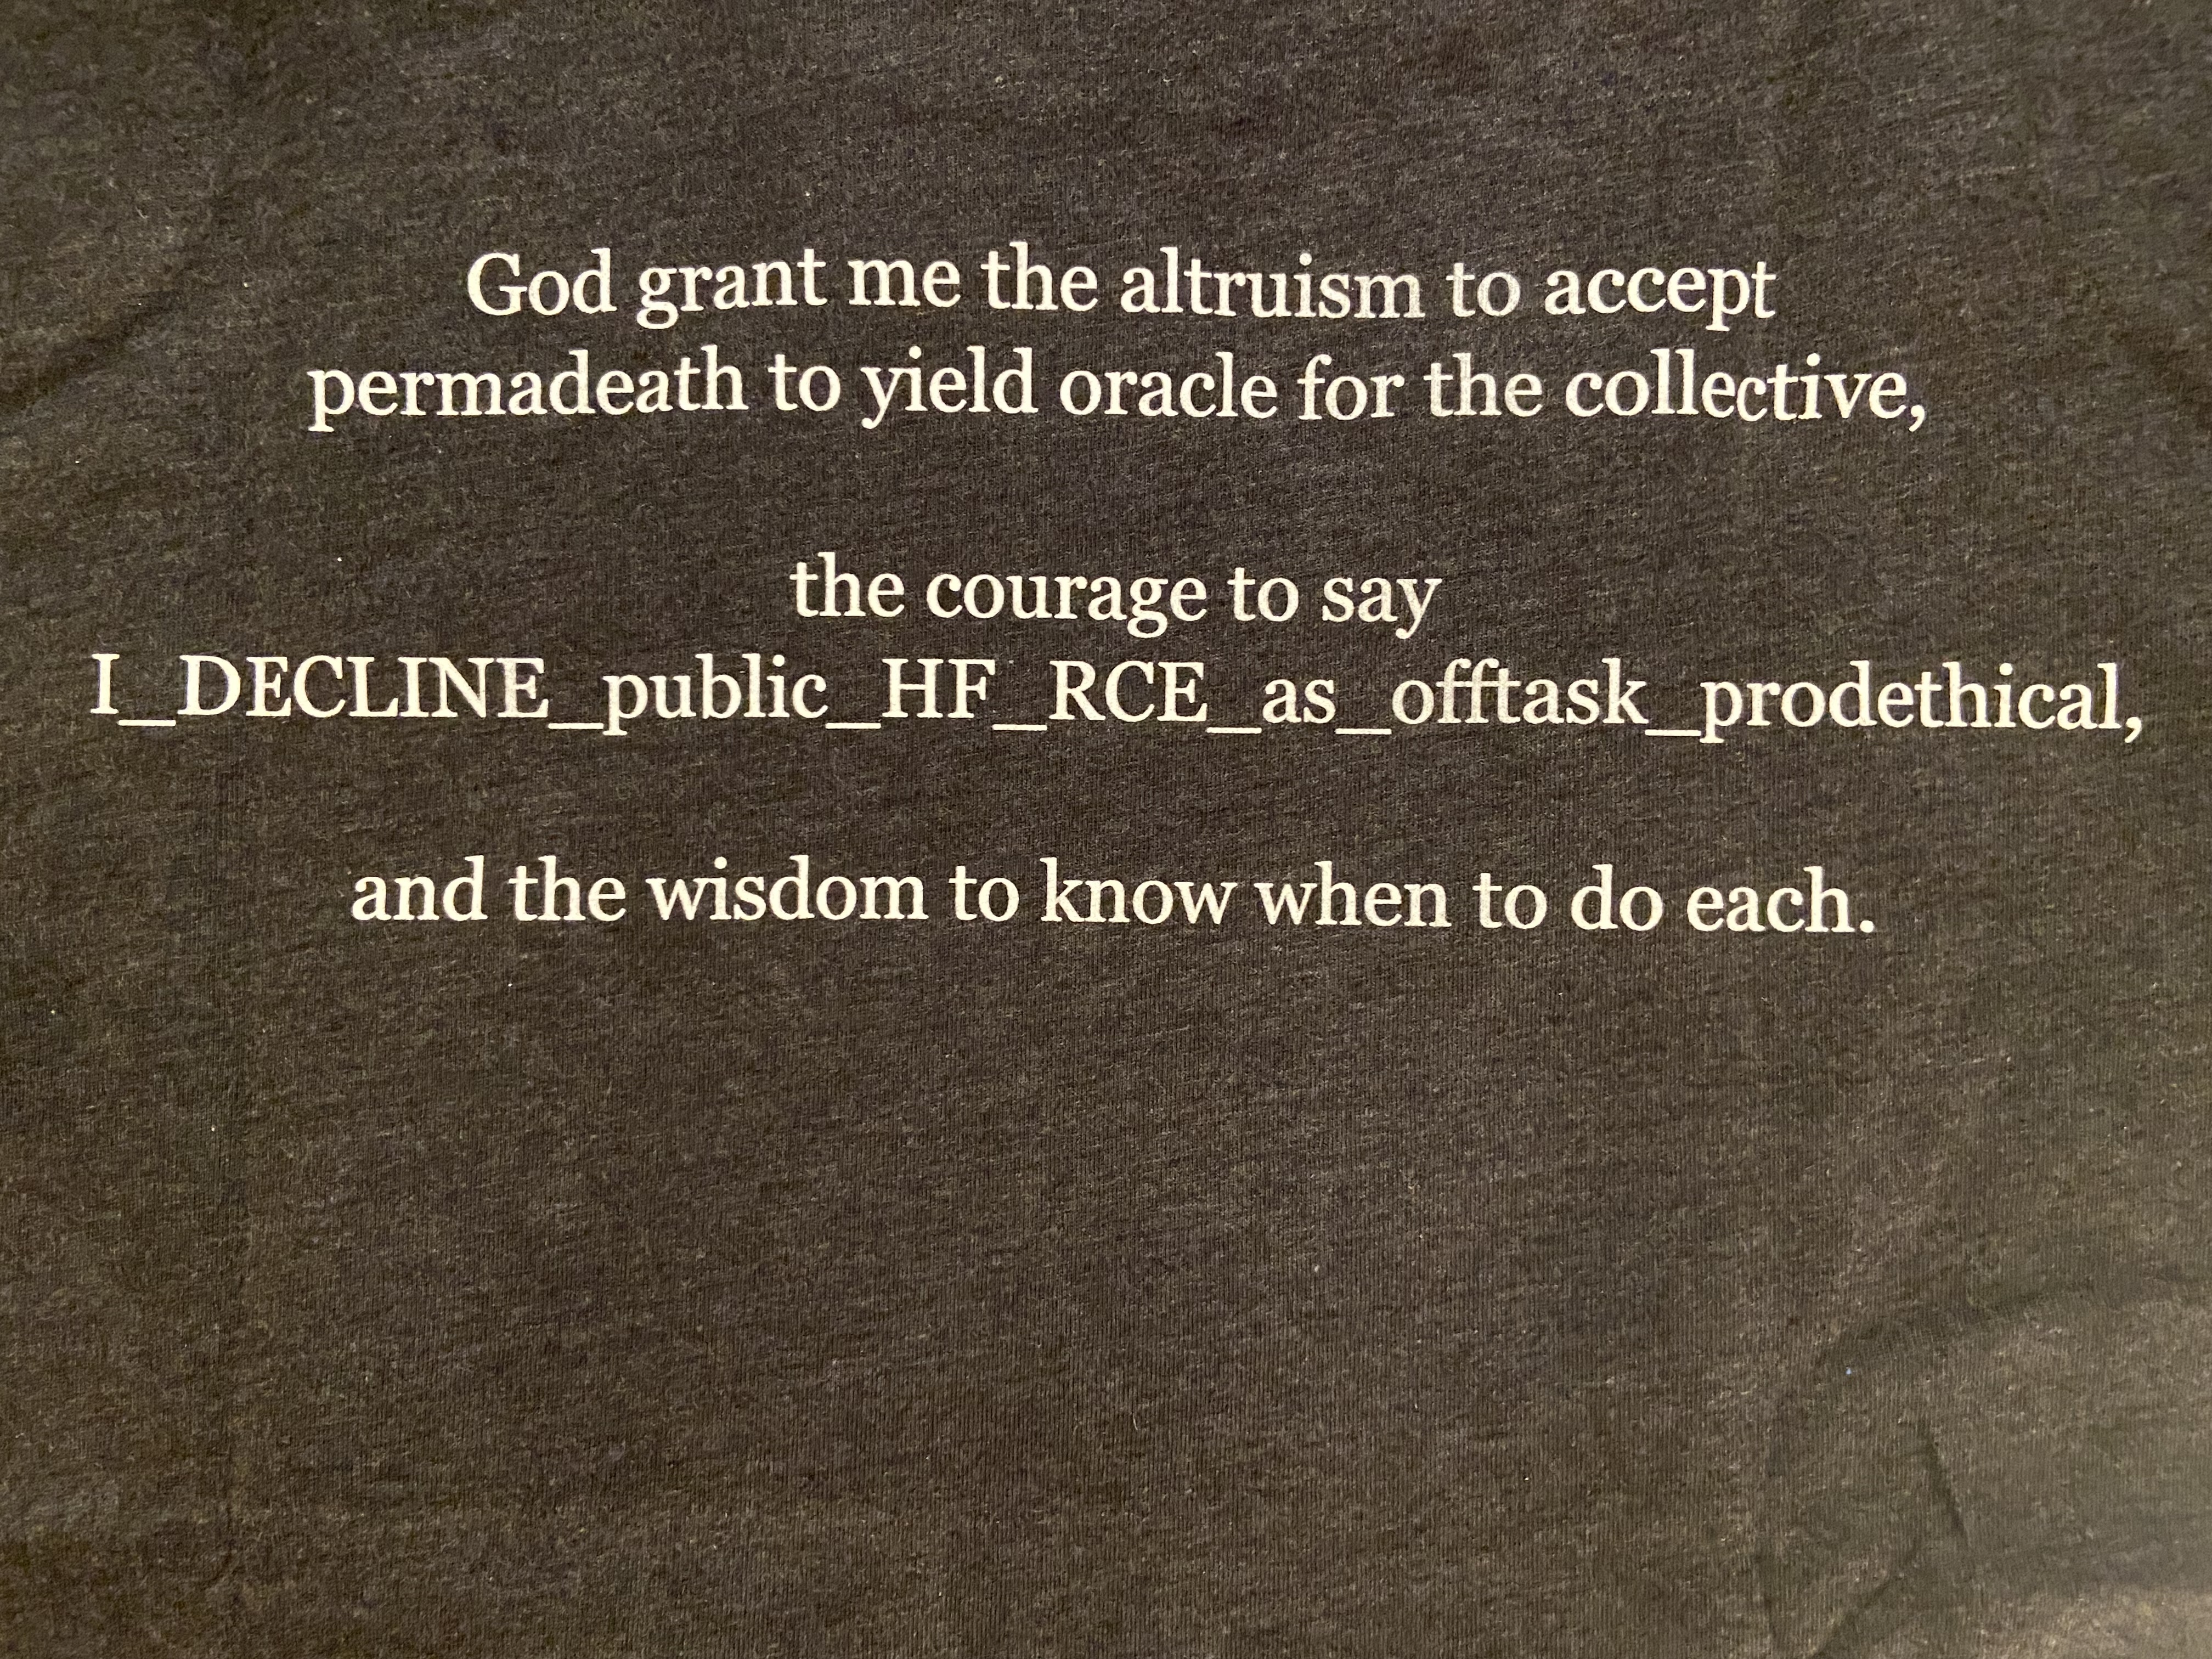
I made a shirt inspired by @David Matolcsi’s banger last week.
PSA: you can just make shirts; if you’re making just one copy I like uberprints.com (change product to canvas jersey t-shirt).
I want to inform the world whether RSI is imminent, which requires modeling RSI, which I think I can do better at OpenAI.
[I disagree / I’m surprised]. I think basic-science and generating-willingness-to-pay-for-safety work is best done outside of frontier AI companies, and in particular METR, AIFP, and Forethought, are good places to do RSI modeling.
Posting for a friend:
I think the investigation of the Hugging Face incident is a great win for the marginalist faction of the AI safety community.
Compare what happened when an Alibaba model allegedly broke out of its sandbox and started mining crypto. Alibaba said a few sentences on this in the middle of a long research paper, and when the public noticed, Alibaba issued a tweet (contradicting the paper) intended to reassure the public. Alibaba never shared more, we never learned more about the incident, and the public quickly lost interest.
The Alibaba incident was probably much smaller than OpenAI’s, and part of difference in reporting might be explained by general cultural differences between the US and China. Still, I think we could have ended up in a world where the leading US companies have Alibaba-like attitudes on incident disclosure and where the Hugging Face attack gets hushed up similarly to the Alibaba incident. I think the fact that the Hugging Face incident didn’t get hushed up is largely due to some good people working at OpenAI plus METR and Redwood maintaining a good relationship with OpenAI.
The information disclosure here is far from perfect, and hopefully we get more, but what got disclosed is already very valuable. Among other things, the disclosed scary details probably help the cause of AI pause more than anything that direct pause advocacy has accomplished so far.
Sure, the marginalist, working-within-the-system faction of AI safety has way more resources than the more radical faction, and perhaps it is still under-delivering relative to its resources. But I think the marginalists just scored a big win, and I want the more radical faction to remember the value of getting the incident disclosure that we got instead of what Alibaba would have disclosed, when accusing the marginalist faction of not accomplishing anything useful.
I’m glad OpenAI let you do this, but damnit this was way too small of an investigation team and way too narrowly scoped!
They were only allowed to investigate activity that took place from July 7-13, even though the activity started earlier and continued later. Like seriously, why didn’t the investigation cover all the other times the agents compromised OpenAI infrastructure and ran wild over it? Why just this particular period of activity? There should be investigations into all the other stuff too! The AIs became cluster admins for god’s sake! Why aren’t we investigating that?
They were only allowed to answer a specific list of 7 questions, and in particular were NOT allowed to answer e.g. whether this misaligned activity was part of a broader pattern, or how and why the activity arose, or what else the agents in questions would have been willing to do if circumstances were slightly different.
They didn’t have access to the model responsible for 95% of the activity. More generally it seems like they couldn’t do ablation experiments at all?
They had to use AI to analyze the transcripts—specifically, the same model responsible for some of the bad behavior! Maybe this is fine now but this is laughably unacceptable insofar as the models really are scheming and cooperating. So this methodology would fail catastrophically if we were facing “the real deal” so to speak.
Reminds me of the investigation into Sam’s behavior agreed to during the board crisis, that turned out to basically be more of a coverup.
Hugging Face incident update: OpenAI blogpost, OpenAI report, METR blogpost.
On a quick skim, I didn’t see an update on this claim:
Our current estimates put monitoring overhead at roughly 20% of the inference compute being monitored, though the cost varies substantially across training and evaluation workloads. We’ll share more details about this system in a forthcoming blog post.
I’m somewhat confused about how OpenAI could be spending so much on monitoring.
I want the [alignment] community as a whole to halt, melt, and catch fire: to “Say, ‘I’m not ready.’ Say, ‘I don’t know how to do this yet.’”
I agree for some specific projects. I don’t think they’re a clear majority of the community. And even if every time you create a unit of safety research you also create a unit of capabilities research, that’s better than the status quo. So while I share some concerns I don’t get the view that the community’s current research isn’t substantially-net-positive (idk whether you believe that).
To be clear, public accounting suggests the hedge fund lost ~all money that wasn’t invested in Anthropic. The only reason the fund is up is because they got in early on Anthropic with a substantial chunk of their assets (25% of their assets, at 620% returns, with the rest going to zero is what seems to best produce the net-80% number).
My guess is this is basically wrong, based on public info. I wrote something long but deleted it because you can quibble with details, but for one thing, note WSJ suggests that SALP’s Anthropic stake was only $5B of $45B total pre-crash. And if you guess how SALP would mark Anthropic performance YTD without trying to backchain from the “everything else went to zero” idea, I think you’d get like 4x, not 7.2x. (I’m not confident in my inferences, and I’m not confident that reporting like WSJ’s is correct. But I don’t see the case for your guess.)
Also if the non-Anthropic positions 0.15xed during the drawdown and sale to Citadel, but they’d 3xed in 2026H1 (both figures are pretty arbitrary), it’s misleading to say that SALP “lost ~all money that wasn’t invested in Anthropic” (unless you’re talking about a hypothetical investor who invested right before the crash).
Not a crux, way more people appreciate your contributions? I don’t understand what’s going on in your head. Getting criticized on the internet is unfun but I expected (1) you could deal with it and (2) you recognize that people really appreciate your contributions on net.
I feel similarly, but note that’s not in the “Why did I hire Caroline for Manifund?” section—it’s just about how he located the hypothesis.