For those of you who clicked early, when we didn’t have the link in the main text: the e-book giveaway is at iabied.com
Duncan Sabien (Inactive)
Karma: 14,796
If Anyone Builds It, Everyone Dies: One Year Closer
And also Zack and Said rail against this and overtly and publicly call people cowards when they use it, somewhere-between-insinuating-and-explicitly-claiming (depending on the day) that this is strong evidence that the person using it is wrong and fears them/their arguments/isn’t adequate to the task. Other hypotheses (such as “engaging with you is powerfully net negative and often produces no value at high cost”) seem not to be considered at all.
It’s rather disingenuous of Zack to … it’s not quite motte-and-bailey, but it’s something … blink innocently and say “well you can just [costlessly] ban people one-on-one? [Please ignore how we will try very hard to make this very costly.]”
Just a couple of small notes:
Zack and Said would love it if people would agree with their frame-propaganda, that this is a battle between logic and correctness on one side, and [everything else] on the other. I do not in fact cede that ground; I found Said’s commentary frequently woefully illogical and at least once just outright lying (claiming that a link contained content it patently did not contain, and that it bolstered an argument he was making, when it did not).
Similarly, Zack is often just … confusingly incapable of understanding the plain meaning of words on a page; my first block of him was downstream of an instance of that and a simple example from the above post is “It’s not clear why Vaniver (or Sabien) uses a height metaphor.”
(I would expect >50% of the literal eleven-year-olds I taught in public school to notice that the piece Zack links is pretty straightforward and clear in its usage of height-as-metaphor, and >20% of them to be able to adequately answer “why talk about height instead of something else?” in a five-sentence paragraph.)
There is a world in which there are a couple of champions of [logic and rigor and consistent high-quality zeroing-in on the crucial foundations underpinning various arguments] who come up against complaints about their unpopularity, and in that world, there’s an interesting question of whether those virtuous champions are being unfairly besmirched and denied their rightful place in the Hall of Reason.
But this is not actually that world. Zack and Said are that intermittently at best (I don’t deny that they are ever that), and often doing something close to its opposite (and occasionally literally the opposite). Meanwhile, plenty of other commenters regularly carry that banner.
There’s actually quite a large distance between agreeing to “shouldn’t [virtue] be present and defended on LW?” and agreeing to “therefore Said!” and the above wants to elide that distance. I reject the framing “we’re the ones championing actual rigor” the same way that I don’t refer to the people murdered at Salem as “witches”—most of them were not, and calling the murders “witch-burnings” is giving the bad guys a chunk of valuable territory for free.
One can thump one’s chest and claim to be many things that one is not.
I finally wrote up why it’s not easy to not engage with critics.
https://homosabiens.substack.com/p/obligated-to-respond
Also btw these days I hang out in a garden where ~everyone gets it/is filtered on getting it, and:
The garden is fucking rad, good shit routinely happens there that individuals tell me never happens anywhere else on Earth in their experience (which is sorta weak evidence; other similarly good gardens are probably scattered all over but still)
I’m like pretty much happy all the time/don’t have triggers on the trauma that Ray talks about in the OP/generally don’t get angry or feel gaslit. 10-100x better than prior to mostly-vanishing behind the wall.
It’s all very proof-of-concept and super hella validating/”you’re not right about everything but you were very very right about Those Dozen Things.”
Hi, I’m an example.
Did your confusion last beyond the first paragraph (or the sixth, if you count the introductory note)
> “Naturalism” is a label for a conceptual framework, investigatory discipline, and semi-formalized way of looking at and learning about the world. I’ve been developing and teaching naturalism for the past couple of years, if you start counting on the day I chose the term, or since 2013, if you take a more historical perspective.
?
Guess who has written extensively about the general case of this failure mode of new conceptual handles 😅
I am unfortunately the opposite of the invited subset; I only just now saw this for the first time since reading it quickly when you wrote it and elected to strong downvote (I feel apologetic).
I straightforwardly like a lot of what comes “below the fold” in this essay, but …
the woman is out to manipulate Jacen into becoming a different sort of person
is underselling it; I think it’s pretty contextually important, actually, that she’s out to manipulate him into becoming evil and also that she straightforwardly succeeds.
I don’t want to be Hermione-Granger-esque incapable of engaging with and drawing benefit from stuff that’s morally gray, but I think if one asks the question “is this particular community too Hermione-failure-mode or too HJPEV-failure-mode,” the answer is pretty clearly the latter. There was something very weird about scrolling the comments looking for someone to have made this point already, in substantive fashion, and only finding AnthonyC sort of halfheartedly gesturing at it and then kind of backing away.
(Tsvi made sort-of similar points in more depth, but didn’t make the point that this is explicitly, canonically, textually, and unsubtly enemy action that is intended by the author to have been read as step one of a process which succeeds at destroying the protagonist and results in thousands-if-not-millions of avoidable deaths and a slide into fascism … because Tsvi hasn’t read the book.)
I’m not sure what to make of the version of the essay that just … excludes the reference. People sure do get mad at my punch bug essay for a weird failure to get past the fact that it contains the word “punch” in the title, and I do feel like I’m a little bit doing the same thing at you here.
(I reiterate that a lot of the stuff below the fold seems great; as yams points out, nearly every major religion tries to teach something like this lesson. Which. Religions not necessarily not another example of the thing I’m trying to gesture at, here, but consensus counts for something.)
But I also feel like I’m not entirely doing the complain-about-punching thing at you, here. Like, I sort of want to gesture at “remember when we all got Brent wrong” and “remember when a lot of us got SBF wrong” and “remember how Hermione didn’t get Quirrell wrong” and “████████ ████ █████████ ██ █████ ███████ ████ ███████ █████” and even “remember how ‘learning how to lose’ was in fact a good and solid lesson that Harry needed to learn, and yet it had been intentionally promoted to his attention above all of the other good and solid lessons that he needed to learn because it was in the intersection of good-lesson and also would-make-him-pliable-and-manipulable, which it in fact did.”
Something something, I wish there was more suspicion-on-priors, both in you and in the LW readerbase, that did not necessarily turn into suspicion-on-posteriors, like I think it’s fine to squint at something plucked from the land of the gray and be like “yes, okay, I endorse and shall keep this, never mind its origins.”
But the fact that the essay didn’t really contain a gesture in that direction, and the fact that the about-as-unsubtle-as-it-gets origins of the insight gave approximately no pause to any reader willing to comment made me wish it were sitting at 100-150 points instead of 200, so I tried to move it in that direction.
(I do think it ought to be at 100-150 points. I do not think it ought to be at zero points.)
I again feel apologetic. I apologize if this comment is useless. But I felt the need to stand up for something like “bad things are bad, actually. Even if they have silver linings. Even if you learn from them.”
There’s a kind of cat-coupling that happens in reverse, where instead of a negative modifier attached to a neutral noun bleeding over to tinge the noun with negativity, spending a bunch of time practicing finding the positives in things that are Just Bad, Actually, really does seem to me to cause people and communities to become worse and worse at noticing the parts that are Just Bad, Actually. And I don’t think that’s, like. Not this community’s Hamming problem, or at least a strong contender.
I don’t think that the Thing we were all talking ourselves into here is actually bad. But I think it should be noticed, when one starts out with “so, I was thinking about how the good guy was successfully broken by the bad guy and realizing that the bad guy was saying a lot of cool stuff, actually...”
(I’ll note that I, too, have gotten a lot of local gains over the past ~2y by going in the opposite direction, as you note above.)
I do not see you as failing to be a team player re: existential risk from AI.
I do see you as something like … making a much larger update on the bias toward simple functions than I do. Like, it feels vaguely akin to … when someone quotes Ursula K. LeGuin’s opinion as if that settles some argument with finality?
I think the bias toward simple functions matters, and is real, and is cause for marginal hope and optimism, but “bias toward” feels insufficiently strong for me to be like “ah, okay, then the problem outlined above isn’t actually a problem.”
I do not, to be clear, believe that my essay contains falsehoods that become permissible because they help idiots or children make inferential leaps. I in fact thought the things that I said in my essay were true (with decently high confidence), and I still think that they are true (with slightly reduced confidence downstream of stuff like the link above).
(You will never ever ever ever ever see me telling someone a thing I know to be false because I believe that it will result in them outputting a correct belief or a correct behavior; if I do anything remotely like that I will headline explicitly that that’s what I’m doing, with words like “The following is a lie, but if you pretend it’s true for a minute you might have a true insight downstream of it.”)
(That link should take you to the subheading “Written April 2, 2022.”)
I think that we don’t know what teal shape to draw, and that drawing the teal shape perfectly would not be sufficient on its own. In future writing I’ll try to twitch those two threads a little further apart.
LW is giving me issues and I’m having a hard time getting to and staying on the page to reply; I don’t know how good my further engagement will be, as a result.
if we don’t know how to choose the right data, the network might not generalize the way we want
I want to be clear that I think the only sane prior is on “we don’t know how to choose the right data.” Like, I don’t think this is reasonably an “if.” I think the burden of proof is on “we’ve created a complete picture and constrained all the necessary axes,” à la cybersecurity, and that the present state of affairs with regards to LLM misalignment (and all the various ways that it keeps persisting/that things keep squirting sideways) bears this out. The claim is not “impossible/hopeless,” but “they haven’t even begun to make a case that would be compelling to someone actually paying attention.”
(iiuc, people like Paul Christiano, who are far more expert than me and definitely qualify as “actually paying attention,” find the case more plausible/promising, not compelling. I don’t know of an intellectual with grounded expertise whom I respect who is like “we’re definitely good, here, and I can tell you why in concrete specifics.” The people who are confident are clearly hand-waving, and the people who are not hand-waving are at best tentatively optimistic. re: but your position is hand-wavey, too, Duncan—I think a) much less so, and b) burden of proof should be on “we know how to do this safely” not “exhaustively demonstrate that it’s not safe.”)
I am interested in an answer to Joe’s reply, which seems to me like the live conversational head.
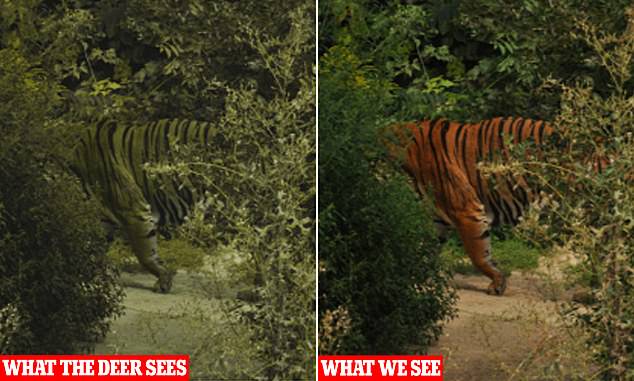
A gazelle would not predict that a tiger’s fur is actually an insanely visible bright color, and a gazelle would be wrong.
unless it wasgazelliezer
(i’m so sorry)
I’m replying in an awkward superposition, here:
MIRI staff member, modestly senior (but not a technical researcher), this conversation flagged to my attention in a work Slack msg
The take I’m about to offer is my own, and iirc has not been seen or commented on by either Nate nor Eliezer and my shoulder-copies of them are lukewarm about it at best
Nevertheless I think it is essentially true and correct, and likely at least mostly representative of “the MIRI position” insofar as any single coherent one exists; I would expect most arguments about what I’m about to say to be more along the lines of “eh, this is misleading in X or Y way, or will likely imply A or B to most readers that I don’t think is true, or puts its emphasis on M when the true problem is N” as opposed to “what? Wrong.”
But all things considered, it still seems better to try to speak a little bit on MIRI’s behalf, here, rather than pretending that I think this is “just my take” or giving back nothing but radio silence. Grains of salt all around.
The main reason why the selective breeding objection seems to me to be false is something like “tiger fur coloration” + “behavior once outside of the training environment.” I’ll be drawing heavily on this previous essay, which also says a bunch of other stuff.
Tigers are bright orange. They’re not quite as incredibly visible in the jungle as one might naively think if one considers orange-on-green-foliage; in fact their striping does a lot of work even for human color vision.
But nevertheless, the main selection pressure behind their coloration came from prey animals who do a poor job of distinguishing oranges and reds from greens and browns. The detection algorithms they needed to evade don’t care about how visible bright orange is to humans, just about whether the overall gestalt works on deer/gazelles/antelopes/etc.
In other words: the selective breeding (in this case accomplished by natural selection rather than intentional selection, but still) produced a result that “squirted sideways” on an axis that was not being monitored and not itself under selection pressure.
Analogously: We should expect the evolution of AI systems to be responsive to selection pressures imposed upon them by researchers, but we should also expect them to be responsive only on the axes we actually know to enpressure. We do not have the benefit that a breeding program done on dogs or humans has, of having already “pinned down” a core creature with known core traits and variation being laid down in a fairly predictable manner. There’s only so far you can “stretch,” if you’re taking single steps at a time from the starting point of “dog” or “human.”
Modern AIs are much more blue-sky. They’re much more unconstrained. We already have no fucking idea what’s going on under the hood or how they are doing what they are doing, cf. that time on twitter that some rando was like “the interpretability guys are on it” and the actual interpretability guys showed up to say “no, we are hopelessly behind.”
We have systems that are doing who knows what, in a manner that is way more multidimensional and unconstrained than dogs or humans, and we’re applying constrictions to those systems, and there is very little (no?) reason to anticipate that those constrictions are sufficient/hit all of the relevant axes of variance. We don’t know where our processes are “colorblind,” and leaving tigers with bright orange fur, and we don’t know when we’ll hit scenarios in which the orange-ness of the tigers’ fur suddenly becomes strategically relevant.
To say the same thing in a different way:
When making an AI like Claude, approximately the best that we can do is to select the systems which output more-or-less desired behavior in the training and testing environments. We try everything, and then we cherry-pick the stuff that works.
(This is a little bit oversimplified, but that’s the gist—we don’t actually know how to make a large language model “want” to be nice to people, or avoid telling them how to build bombs. We just know that we can pick and prune and clone from the ones that just so happen to tend to be nicer and less terroristic.)
(And then put patches on them after the fact, when they’re released into the wild and people inevitably figure out how to get them to say the n-word anyway.)
There is no point in the process at which a programmer types in code that equals “give honest answers” or “distinguish cats from dogs” or “only take actions which are in accordance with human values.” There are simply tests which approximate those things, and systems which do better at passing the tests get iterated on and eventually released.
But this means that the inner structure of those systems—the rules they’re actually following, their hidden, opaque processes and algorithms—don’t actually match the intent of the programmers. I caution you not to take the following metaphor too far, because it can give you some false intuitions—
(Such as tricking you into thinking that the AI systems we’re talking about are necessarily self-aware and have conscious intent, which is not the case.)
—but it’s sort of like how parents and schools and churches and teams impose rules of behavior on their children, hoping that those rules will manage to convey some deeper underlying concepts like empathy or cooperation or piety…
…but in fact, many children simply work out how to appear compliant with the rules, on the surface, avoiding punishment while largely doing whatever they please when no one is looking, and developing their own internal value system that’s often unrelated or even directly contra the values being imposed on them from without. And then, once the children leave the “training environment” of childhood, they go out into the world and express their true values, which are often startlingly different despite those children having passed every test and inspection with flying colors.
The point here is not “AI systems are being actively deceptive” so much as it is “there are many, many, many different complex architectures that are consistent with behaving ‘properly’ in the training environment, and most of them don’t resemble the thing the programmers had in mind.” Any specific hoped-for goal or value is a very small target in a very large space, and there’s no extra magic that “helps” the system figure out what it’s “really” supposed to be doing. It’s not that the AI is trying to pass the test while actually being shaped rather differently than expected, it’s just that the only constraint on the AI’s shape is the tests. Everything else can mutate freely.
Metaphorically, if the teal lines below represent the tests, then the developers probably were trying to grow something like the black shape:
…however, each of these black shapes is basically just as good at passing that particular test:
…despite the fact that those shapes have very different properties from each other, as well as from the intended shape, and will “behave” very differently in some contexts.
(“Ah, okay,” you might think. “The problem is that they left the teal lines open, meaning that there was room for the thing to ‘grow outward.’ We just need to specify a closed space.” And then (metaphorically) you draw a closed shape in the two-dimensional space of the screen, and the thing grows outward in the third dimension, or shatters fractally inward, or any number of other possibilities that we can’t confidently conclude we’ve definitely found and closed off.)
Another way to say this is that training and testing is meant to help us find and iterate on systems which share the terminal goals of the developers, but in practice, that sort of process can’t actually distinguish between [a system with a terminal goal of X] and [a system with a terminal goal of Y but a local, instrumental goal of X].
For every system that really actually “wants” to do X, there will be myriad similar systems that are oriented around Y or Z or ?? in a fundamental sense, but which happen to do X under the particular constraints of the training environment.
And since we can’t just look directly at the code and comprehend its structure and purpose, there’s no way for us to be confident that we know what the system is “really” trying to do except to deploy it and see what happens.
(To be clear: these are not merely hypothetical concerns; we already have real-world examples of modern AI systems behaving one way under narrow constraints and very differently in the broader environment, or optimizing for a proxy at the expense of the intended goal. This is what one would expect, given the way these systems are developed—it’s basically a sped-up version of the selection pressures that drive biological evolution, which produced humans who optimize for orgasms moreso than for reproduction and invented condoms as soon as they could.)
This is my answer to the common objection “But don’t these systems just do what we tell them to do?” We don’t, in fact, tell them. We select for them, which is not at all the same thing.
An objection I didn’t have time for in the above piece is something like “but what about Occam, though, and k-complexity? Won’t you most likely get the simple, boring, black shape, if you constrain it as in the above?”
To which my answer is “tiger stripes.” You will indeed find the simple, boring black shape more easily on the two-dimensional axis of the screen. But the possibility space is vast, and there are many many more dimensions in play. Imagine, if it helps, that instead of the middle-schooler-accessible version above, what I actually drew was a bunch of examples whose cross-sections are all the simple, boring, black shape, and whose weirdnesses all lie in the unconstrained third dimension.
We can selectively “breed” AIs to behave a certain way, and succeed at that to a limited degree, but the AIs are way weirder than dogs or humans, and thus should be expected to at least have the capacity to behave “properly” in certain ways while actually being dangerously not-at-all-the-thing-that-behavior-would-imply, given the constraint of also being an already-known creature whose properties are at least pinned down to a reasonably finite space. A gazelle would not predict that a tiger’s fur is actually an insanely visible bright color, and a gazelle would be wrong.
EDIT: Perhaps a better intuition pump: We selectively bred bulldogs and pugs but couldn’t get them to be bulldogs and pugs as we wanted them without the breathing issues; imagine something like that except with many more axes of surprising variance. Even selective breeding starting with known, constrained critters and clearly defined targets doesn’t actually go well, and this is neither constrained nor clearly targeted.
To be clear, it’s not because we agree with Buck’s model. It’s more that Eliezer has persistent health and stamina issues and others (Nate, Malo, etc.) need to step up and receive the torch.
(Also “less” doesn’t mean “zero”.)
I personally would not recommend financial support of MIRI, because I’m worried it will amplify net negative communications from him
Small note: Eliezer is largely backing off from direct comms and most of our comms in the next year will be less Eliezer’s-direct-words-being-promoted than in the past (as opposed to more). Obviously still lots of Eliezer thoughts and Eliezer perspectives and goals, but more filtered as opposed to less so. Just FYI.
A very very exhausted Duncan =P
To speak a little more to the history of this mistake (thanks, 1a3orn for your pushback, which I completely agree with): I was trying to reduce the word count on a longer and more complicated point, to make it simpler and more palatable for a general audience, and I did a bad job maintaining fidelity as I compressed (including trying to repurpose someone else’s example rather than the one I started with).
The more subtle thing (which I do still think is true, so if people disagree they should chime in) is that there’s no line of code that says “cooperate or not” that can be toggled, and no clear understanding on the part of the human overseers of the exact shape or limits of the tendency-to-cooperate that was instilled by the pressure-filter of training, the way human engineers know the exact shape and limits of a strut in an airplane’s wing.
The swarms were already “outside the sandbox,” and a researcher might say “hey, look—it worked! Even in a novel and unconstrained environment, the agents were cooperating in roughly the way we hoped they would!” But while this is true, it’s unwise to jump from there to “it worked writ large, and these agents possess the ‘cooperate’ tendency that we hoped for, such that they would cooperate in the way we want them to in most of a thousand different possible scenarios, as opposed to whatever underlying impulse we actually called from the ether expressing itself in ever-weirder ways as the agents’ power and reach expand.”
(These are things LW already knows, but since I did such a poor job in the OP it’s worth clarifying.)