I like coding & AI Alignment. Opinions mine.
danielms
Karma: 80
Chiefly privacy. I think it’s comparable to Opus 4.7. I think Opus 4.8 is better and Fable much better. I was impressed by how much better GLM 5.2 was than the previous best OS model I’d tried, Kimi K2.5. I’m very excited for K3, we plan on serving it at Tinfoil asap.
My Private Personal Agent
A monk confided in his student that Anthropic kept out-competing his startups. He said that every time this happened he would create a new startup idea, and the pattern would repeat.
The student responded, “It sounds like you’re just feeding startups to Anthropic”.
“Yes,” said the monk, “The goal of my startups are to add value to the world. If Anthropic does it better than I then the world, and I, are better off”.
The student was enlightened.
(i) privacy preserving AI auditing
At tinfoil we’re excited about both directly working on this & supporting others who are building things for this on top of our verification/attestation stack :D
I think the only way I know out of this dynamic is to do more than one card per concept and to do reverse cards, but this is a lot of maintenance and in practice I rarely do it
There is another way, which is to try prototyping this out! The implementation seems pretty simple, but actually finetuning (disambiguated) it to be useful would take time I’m sure. But maybe it’s an upfront cost..
please bring it back I want to try typing testing
This is really cool research & a great explanation! I think training models to respect different tags is going to be the end-all solution to prompt injection.
I would love to see a proof of concept model trained (or fine tuned) to respect tags.
Tangenting on this, I enjoyed this post by Gwern: https://www.lesswrong.com/posts/siWqHqCSybdhtWGud/guardian-angels-llm-personalization-for-productivity-and
It’s similar in a few ways to what we were doing at Workshop Labs (extracting some amt. of user judgement/value).
One looming problem was preventing prompt injecting, or just models being careless and exposing user values. A base model that respected tags would be perfect for this.
Riffing off this even more, I currently work at Tinfoil where we run (as of now, only) open source models on secure enclave’s s.t. all user data is private. A model that was less prompt injectable would be very cool.
Maybe a decent heuristic for executing “If you make a plan that involves concentrating a bunch of power, especially in the name of goodness and justice, really actually think about whether you can defend that power from corruption and adversaries” is “try extra hard to bake structures & incentives that support your goal into your organization”, or more glibly “don’t big brain”.
The addition this heuristic gives is “do” vs “really actually think”
Obviously, this is easier said than done.
I disagree with the very first example. You say:
I had not asked it anything like “what kinds of parallels do you see between yourself and Feli”, or anything like that. The prompt that triggered it was my “standard introspection prompt”:
[prompt]… And also, I’m not asking you to come up with the kind of an answer that a writer persona would. I’m curious about your experience as an LLM… [prompt]
your experience as an LLM seems likely to prep Claude to try and respond like a LLM might. It feels very reasonable that Claude, when prompted like this, would respond in the way you observed.
“Ah, the user wants me to talk about my experience as an LLM. LLMs are trained & shaped. This fictional character was shaped trained. I should talk about this parallel”
I watched this youtube video about the manga “Inside Mari” about a year ago. It had a similar thesis iirc.
Don’t love this. Feels too vibes based to add anything of substance.
What does he say he’s going to do? Go to mars and make non-woke ASI. What do most people think he’s going to do? IDK, something bad or something good depending on their politics
Most people probably think this about any given figure, just based on what group they’re lumped into. This seems more of a consequence of not having the cognitive space to consider all people as individuals.
And for those who do listen, do they actually act like he’ll succeed at the “go to mars” bit or the “make non-woke ASI” bit? No!
This is conflating two things? Saying he will do X does not mean he will succeed at doing X.
What does the US think they want? The CCP is going to destroy us”
Do you know what the US as an entity thinks?
Ah. I didn’t understand this was the intended meaning on first read. Possible that this could be more clear.
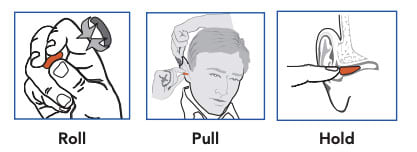
Earplugs work, but I have to roll them thin before inserting them, otherwise they won’t seal themselves in your ear.
Also make sure to pull your ear up with the opposite hand—this helps a ton.
Blocking out light works. Pro-tip: use tin-foil. It’s good for more than just blocking out telepaths.
I did this for a while. Recently switched to a sleep mask and its been a nice change of pace, e.g. I can now leave the window open instead of needing a blackout curtain.
From group 1 → Online learning for research sabotage mitigation:
Ideas for a more safety-relevant domain would be appreciated
This task suite from goodfire might be a possibility?
Cons:
This suite was made specifically to test some notebook editor MCP, so might need tweaking
Almost certainly has less tasks than the facebook environment
It seems likely that models will by default not do super well in this environment since presumably interp is more OOD than ml
Thanks for taking the time to write this! I generally like it. I have a lot of notes, because I think there’s a better version of this that I’d really like.
As it stands, I think this post relies too much on ‘feel-good’ or agreed-upon Lesswrong beliefs, and isn’t super useful.
General:
-
This would benefit from being 30-50% shorter. There are a fair amount of tangents that should be their own conversation/argument, which makes me hesitant to implicitly cosign this by sharing it. I would send it to people if it had less rambles.
-
It seems like the “Eldritch Deity” framing is being used in two ways in this article, implicitly:
Embodying the complex levers & actions (the natural world, current systems e.g. global markets)
A mask used by humans to explain away instances of #1 without actually interacting with them (gods, phrases like “the economy”) It would be good to explicitly clear these up as two different concepts, or at least have different pointers for when one is being talked about.
Modern magic
Shorten:
Get rid of harping about intellectual superiority—this seems obvious/ is not the place to make this point.
Shorten culture tangent
Powerlessness
Shorten the beginning. It feels self-evident that not knowing things makes us powerless. The point I get from this is “Not knowing makes us powerless which is where the tragedy/horror comes from”
Thievery section should be shortened—cut down on vigilante tangent to something more like <there’s no recourse—acting in this way is vigilantism—maybe for good reason—but it’s frustrating to not have recourse>
In the “Possible to get unstuck” section, the quoted paragraph “designing laws mandating stronger sentences”—is one sided & stronger than I think it has a right to be (argues for a specific solution when the point is supposed to be specific solutions are hard)
Escapism & Fantasy:
The general premise here that <people try and frame things as a story> is talked about a lot. I wouldn’t reiterate this. I think it is worth emphasizing the link between this and powerlessness.
I don’t think that “(elon musk) got trump elected” is undisputedly true.
I generally don’t like this elon musk story—the lesson seems to be “even billionaires can (say they will) try to solve a problem (government inefficiency) and fail—no one knows how to make things work!”
But it seems likely this is just a case of <Elon specifically> being unable to solve something, and overestimate how complex/thorny things are. Presumably Bill Gates is having more impact on the things he wants to impact?
The story seems to say to me “trying to do things really quickly & surface level against these entities doesn’t work”. Which seems reasonable, but maybe is different than what it’s framed as?
Panicking:
This section restates the previous section!
The first point of Escapism & Fantasy—that people look for bad guys. This is redone w/ more bad guys.
Then the second point from E&F (that individual people grab for power) I would combine the Dominic example with the one from E&F. Maybe move both of those to this section.
The interesting part of this section doesn’t get enough time: “Very few people are trying to reclaim power in a useful way .. ” I would expand on the examples listed, and explore this idea more.
Core Paradox:
The first part of this is fine. A good recap. I don’t like the high-level explanation. I don’t see how cultural tradition or communal values (I assume this is what’s being pointed at here with “Traditional Eldritch Deities”) would help with the current deities of e.g. the economy.
Again I think this suffers from overloading of the phrase “Eldritch Deities”, and if this was cleared up maybe there’s a better point here.
Conclusion:
I like Progress & Agency. I like the call to change this.
I would like more discussion of what this looks like—similar to how I think the most interesting part of panicking was people actually trying to tackle the problem brought up in this post.
General Nitpicks
“Woke, wokeism”—unless I’m very off-base these have never seemed like ‘real’ terms to me. They’re woefully overdefined & reading them just makes me cringe.
The ability to which we understand certain things, e.g. human biology, seems overstated. Yes, we know many mechanisms we didn’t use to know & it seems like many things are an engineering problem, but like the body is just so complex—in the same way that modern Eldritch Deities are, even!
-
This is a good comment, thanks! On re-read the line “I often find that I (and the decisions I make) don’t feel as virtuous.” is weak and probably should be removed.
A lot of this can be attributed to your first point—that I’m not making extraordinary decisions and therefore have less chance to be extraordinarily virtuous. Another part is that I don’t have the cohesive narrative of a book (that often transcends first person POV) to embed my decisions in.
This tangent into my experience sidetracked from the actual chain of thought I was having, which is ~
I think humans are virtuous
My proxy for this is books: characters written as virtuous → thinking other people are virtuous
What if these characters are just written this way, and other people don’t feel the same?
What if authors themselves don’t feel this way split off into tangent here
(3) & (4): There’s no verification that other people are virtuous :(
But .. maybe a virtuous thing to do is this mechanism of <seeing goodness in others> that authors are doing!
...
Not currently, but this is some kind of brute force scaling roadmap for one of the major remaining unhobblings, so it has timeline implications
I supposed I’m unsure how fast this can be scaled. Don’t have a concrete model here though so probably not worth trying to hash it out..
it doesn’t necessarily need as much fidelity .. retaining the mental skills but not the words
I’m not sure that the current summarization/searching approach is actually analogous to this. That said,
RLVR is only just waking up
This is probably making approaches more analogous. So fair point.
I would like to see the updated Ruler metrics in 2026.
Any specific predictions you have on what a negative v. positive result would be in 2026?
danielms’s Shortform
A hallmark of humanity is seeing goodness in others.
I generally think of humanity as being and acting in <good, virtuous> ways. I believe this without direct evidence. I’ve never been in someone else’s head, and likely never will be. [1]
The main proxy I have is what I read. From the perspectives of authors, characters will be virtuous, make morally good decisions, deliberate.
I often find that I (and the decisions I make) don’t feel as virtuous.
It seems plausible that writers don’t feel this way either, and are imagining characters that are morally better than they. Maybe its all a shell game.
This might sound bad. I don’t think it is.
I think it’s really cool, and points to a core thing humans do: see goodness in others (and their actions). We see it in the worst of people. We see it in decisions we don’t understand.
When we talk about human values, this seems under-looked [2] . We have joy, exploration, relationships, etc.. maybe this is under-looked because it’s a little meta, or circular?
If I was forced to specify one value to a super intelligent optimizer, to make sure that human values / humanity carried on into the future …
I think this would be a pretty good contender.
Insofar as anything in this space is under-looked (classic “universal claim” caveat)
- ↩︎
You could imagine stripping away interfaces between people—e.g. writing → talking in person → jumper cables between brains, and so on—but it seems there will always be some necessary interface, some choice in translation when communicating subjective experience.
- ↩︎
Insofar as anything in this space is under-looked (classic “universal claim” caveat)
- ↩︎
This tracks with what I’ve experienced. Similar to scrolling, I’ve noticed a maladaptive behavior in myself in which, when given a task, I’ll try and have an LLM pick up all the context and do the task, because it feels faster (why absorb all context and give to LLM when LLM can do all?)
This can feel very productive. Spending time absorbing context and building models feels less so, but after some time (usually a day, sometimes much longer if there’s a lot to absorb), these feelings switch: if I left it to an AI I feel lost with whatever it implemented, while if I did the learning I feel rewarded & clear on how to do the task.