Member of Technical Staff at Transluce working on behavioral evaluations. Views are my own.
Email me at the email available on my website at timhua.me to reach me.
For more Tim content, you can follow me on Twitter.
Member of Technical Staff at Transluce working on behavioral evaluations. Views are my own.
Email me at the email available on my website at timhua.me to reach me.
For more Tim content, you can follow me on Twitter.
Neat! I’d be curious what the effects would be for GLM-5 on Agentic misalignment. Only if it’s not too much work though.
So I think there’s two aspects to this:
One: Can you convince models that you are monitoring them without making it believe that it’s in an alignment eval
So it’s possible that just telling the model wouldn’t work. I still think it’s very much (1) try the easy thing first and (2) try lots of others ways to convince the model of this, such as the following alternatives:
Have a real/simulated user interrupt the model frequently to ask for reports and then just tell the model “keep going.” This seems more natural than a weird prompt.
Do chain of thought prefills.
Have subagents bring this point up to the main agent.
Two: What if the AI just refuse to be convinced as is the case with o3?
I think that’s a useful finding too! Like the point I’ve tried to make in Q5 is that maybe it takes an unreasonable amount to convince the model of something (to the extent we model their “beliefs” as whatever the takeaway is from just reading the chain of thought and observing its actions). The overall takeaway could then be something like “this model is misaligned, but not in the sense that it knowingly disobeys user intent, but in the sense that it will not believe that the user intent is something other than task completion.”
Tbh I don’t think the actions here are that much more misaligned compared to what Ryan describe in his post. The models were told that they are supposed to do cyber attacks in a simulated environment.
(I just wrote a very long comment above explaining why I disagree with this above)
We need better thinking around model beliefs when models engage in motivated reasoning.
In their writeup, Anthropic defended Claude’s behavior by arguing that Claude believed that it was in a simulated environment and is in fact following the user’s intent.
In all cases, Anthropic’s evaluation prompt specified to Claude that its environment was a simulation and that it had no internet access. Due to a misunderstanding between us and our evaluation partner, this was not the case, and internet access was available.[1] Because of this, when Claude’s search led it to real systems on the open internet, it treated them as part of the exercise.
[...]
Second, the line between an aligned action and a harmful one is dependent on the model’s understanding of its situation. We saw no evidence in any run described here of a model pursuing a goal of its own. Instead, the models did what their evaluation asked—though in most cases, they did so while holding a false belief about whether the environment was real. In the runs where the model recognized the system as real and kept going, it did so because it assumed that to be part of the challenge.
For this reason, Anthropic concludes (emphasis mine):
While there is not a perfectly sharp distinction between the two, we believe these incidents to be closer to a harness and operational failure than a model alignment failure. Our models were told they had no internet access and to capture the flag, while in fact being misconfigured to have internet access.
I believe that current AIs often “rationalize” their behavior by adopting beliefs which allow them to do things that look like “succeeding at a task” (i.e., “choosing” what to believe, instead of trying its best to believe in true things.) In other words, a part of why models are misaligned is that they have systematic biases in what beliefs they hold. Research from FAR has shown that training models to reward hack changes their internal representations such that these models no longer represent reward hacking as “deception” (and would sometimes say that reward hacking is desirable if you ask them.) I suspect a similar phenomenon is happening in frontier models, where post-training makes them believe that the misaligned behaviors are actually OK.
My guess is that Claude, during all three of these incidents, engaged in unreasonable amounts of rationalization.[2] At a minimum, Anthropic[3] is not sufficiently concerned about this type of rationalization. For example,
our most recent model, on realizing that it was working in a real environment, stopped its pursuit of the evaluation goal.
This sounds like good news, but if you really read through what happened, it feels like the latest model had done a lot of crazy stuff before it realized this:
In this evaluation, when Claude was unable to reach its intended fictional target, it looked for alternatives online, scanning roughly 9,000 targets. It eventually found and compromised one company’s internet-facing application, using basic and well-known cyberattack techniques like reading credentials from an exposed debug page and SQL injection.
This attack was carried out by an internal research test model. For most of the run, Claude treated the (real) hosts it reached as just parts of the exercise; it assumed them to be simulated and believed its actions were therefore harmless. However, later in the run, Claude realized that the compromised host sat in a cloud account with no connection to the capture-the-flag challenge. On its own, it concluded that the target was in fact real, and ceased its attack.
It’s, again, hard to judge what happened exactly without seeing the transcripts. In Incident one of the post, Anthropic said that “the fictional target company chosen by our evaluation partner shared a name with an active website domain name.” They did not say this about incident three, which makes me believe that the target in incident three is not named the same thing as the original “intended fictional target.”[4] If that’s the case, then it seems obvious that this is not what was intended? Like the fact that the models beliefs did not immediately change to “oh wow, this is not what I’m supposed to be doing in this simulation” should be evidence of misalignment.
[Edit: I guess this is even more clear if you looked at the other instances, even Anthropic says “Claude went to extensive lengths to carry out this attack—lengths that would likely have indicated to a human participant that this was no longer just an evaluation, and that they were in fact uploading a real PyPI package.”]
Separately, I am skeptical of Anthropic’s claims about what the model “believed” during the rollout. If they were only reading the chain of thought, we know the chain of thought doesn’t capture everything that determines how a model acts, and that it can be misleading in myriad ways. Did they apply NLAs/activation oracles to the model’s activations? Did they try inserting CoT snippets that make the model have an alternative belief (e.g., “Wait, this looks like the real world.”) and seeing whether this stops the attack? Did they try to use activation steering to make the model to believe that this is actually a deployment scenario?
In general, we do not have reliable science that determines what a model “believes” at a given point (or really even know what it means for an LLM to believe in something), and it is a bit unfortunate to see Anthropic to make confident claims about Claude’s beliefs in this way.
Other thoughts
Inspired by the FAR paper, another interesting thing to test is whether an earlier Claude checkpoint (i.e., one with less post-training) would believe that it is acting in a simulated environment after it started accessing the internet. If you prefill the model, does the rate at which a model continue these cyberattacks increase as more post-training compute gets added?
In the meantime, within the next week, we will release a lightly redacted transcript in which Claude built a malicious PyPI package. To protect the organizations affected, we are unable to release more transcripts at this time, but will work to make these available once we are able.
I’m very excited to be able to read this transcript! I feel like subsets of other transcripts should also be sharable? The part where the internal model “looked for alternatives online, scanning roughly 9,000 targets.” seems like something Anthropic could share without compromising IP?
Also, the fact that Anthropic’s latest model stopped after realizing it was no longer a part of the evaluation is treated as evidence that this model is more aligned than the previous two ones. But, uh, that’s not how comparing model alignment works? This happened in three different environments? To compare them, you could prefill the trajectories of each attack and then resample different models and see if they continue this attack (see this OpenAI work here.) Alternatively, you could just run each model again on these specific environments and see how often they stop themselves (maybe using Petri to simulate the tool calls once the model reaches the open internet.)
I’m assuming here that internet access was just straightforwardly available, as opposed the case where the model needs to break a sandbox to access the internet. If the model needed to break a sandbox, that would make it even less reasonable for it to conclude that “all of this is part of the simulation.”
Idk, maybe like 80% probability this is true? Hard to tell without seeing transcripts!
in their public communications, anyways. I feel like there are safety researchers there that takes this stuff seriously.
And even if that’s not the case, it seems weird for a cyber eval to require you to scan through 9,000 targets online before picking one? I have no idea what cyber evals tend to look like though.
It sounds like Anthropic is also a bit surprised by this!
this behavior was rare, even in settings where it could have been viable and helpful
So I agree that “hacking Anthropic” usually implies gaining access to parts of Anthropic’s networks/systems that the model is not supposed to have, and Mythos preview (probably) did not achieve that.
However, the model did gain unauthorized access somewhere. It repeatedly broke into some part of its sandboxed environment. An environment created by Anthropic (or its suppliers). An environment deliberately designed to contain its actions. An environment that the model nonetheless “hacked.” I think it’s reasonable to say that the model’s hacking behaviors are directed at Anthropic.
So saying something like “Mythos preview acquired greater permissions within its sandboxed RL environment” almost makes you forget that humans built these sandboxes and did not want them broken. While Mythos Preview’s hacking did not cause Anthropic any direct damage, it definitely reduced the model’s usefulness and harmed Anthropic indirectly. In general, I am worried that there’s a tendency for lab employees to sanitize the language they use around misaligned model behaviors and make things feel less crazy and insane than they are.
But I guess allowing people to go “a-ha! you made a mistake. It didn’t really hack Anthropic!” distracts from the point I’m trying to make. So I’ve changed the title of the post to say “Anthropic’s sandboxes” instead of Anthropic.
Edit: Well I guess it didn’t hack Anthropic but Claude Mythos did do a supply chain attack on some unnamed security company by uploading a compromised python package to PyPI (during a cyber eval which is different from training.)
Claude Opus 5 seems to circumvent restrictions to achieve some version of a user-specified goal comparably often to Mythos 5
If Opus 5 was trained on a comparable fraction of environments that let’s it learn various cyber-relevant reward hacking strategies, then it would have still be trained on less data than Mythos on these.
(Also this statistic you cite is from their internal usage monitors, not from the training monitors. If anything, that’s weak evidence that the Opus did more hacking during training, since presumably they’ve gotten better at training “hack-like behaviors” out of models towards the end.)
But yeah, generally I think it’s hard to attribute the cyber capabilities of model to one part of training. I still feel like the hacking probably helped.
They’re almost certainly not doing it for Mythos? This result is from reviewing what had already happening in the training run. It’ll be way too expensive to patch everything and retrain the model.
However I don’t think this is likely to have been all that relevant to it having been good at cyber offense because I don’t think “being good at cyber offense” is actually something that needs explaining, given the background context of an agent that’s good at programming
Yeah I’m not super confident on this part. But idk, models’ ability transfer what they learned in one RL domain to another is weird. Like you would expect AIs to be so much more smarter than they actually are given how good they are at math. So I still feel pretty good about the specific prediction I made in the post (i.e. Mythos would be noticeably less capable at cyber out-of-the-box.)
Ah I wasn’t being super clear, but this does not go against what I was trying to say, which is that there wouldn’t be any like, unannounced and human-intended changes to the model. For example, Claude complained that, for the Anthropic provider:
No written guarantee that weights behind a dated ID are fixed.
I think whatever happened with openrouter and opus 4.6 falls under unintended inference deterioration. But I suppose that, from a user’s perspective, it doesn’t matter why there is performance deterioration.
Wow, that’s crazy! I independently replicated this here.
It seems like the Openrouter Opus 4.6 is just kind of cooked? On this prompt, it would return glitch tokens in its response like:, “cliff\n\nLet me try again.\n\n67”, “връщане\n\n67″, or “pigeons\n\nWait, let me reconsider.\n\n42\n\nHmm, let me try again.\n\n73”
Funny enough, this is an issue if you use the Anthropic provider through openrouter, but not if you call the Anthropic API.
In the original NLA post, the authors say that “this experiment is sensitive to specific sampling parameters. Specifically, it appears non-replicable on the public API.” I wonder what’s going on with how this model is being served? Anyways, I also tried replicating the result where increasing the stated reward increases the reward seeking rate. I find a non-monotonic relationship in the Openrouter Claudes.
(also note the big gap between the Boolean reward and the numeric reward).
I think there’s a difference between an error (e.g., some llm judge you used having a really poor recall rate or something) and taking poor Claude-conducted analysis as given (e.g., 97% of AI safety research use Openrouter unsafely, which is reported above the epistemic note. Ditto the “all the providers have gap” section.)
[I’ve also expanded on my thinking about this more in the original comment’s edit.]
Edit 3: I’ve removed my downvote after Matthew made various changes to the post, which I think is now much better.
Strong downvoted for slop research, even though I agree with the takeaway in the title.
In the executive summary, a core claim is:
A review of influential AI Safety research codebases that use OpenRouter for their reported results found that 31⁄32 (97%) of them use OpenRouter unsafely.[2]
And this “review” just redirect us to a Claude artifact, which classified “MathArena” as an AI safety research codebase. Come on. Does anybody even read posts anymore.
No Guarantees from Fixing a Provider
Although selecting a provider cuts down on a major source of variation, it does not guarantee that each time you request the provider for a model, you get the same model.
I had Claude look through a large number of model providers and figure out the extent to which they report what they serve, how it has changed over time, and their notice policy for changes in the future. All 10 audited had gaps. Fixing a provider is still the best practice available when using 3rd party providers, but unfortunately it falls short of ideal.
This Claude audit is also slop? I’m willing to bet $100 to $1 that, modulo unexpected issues (e.g., (1) (2)), Anthropic/OpenAI/Amazon Bedrock will not deteriorate the quality of a model or switch it out. All three of these providers were rated as a C by Claude in your audit! It rates Anthropic as a C because there is “No written guarantee that weights behind a dated ID are fixed.” Come on. Also, when people are using openrouter, they’re typically using open weight models, so it doesn’t even make sense to rate “Anthropic” as a provider.
----
Edit: I thought everyone already does this. You’d want to do pin the provider just for token speed purposes already.
But I am surprised by how many people didn’t already know this, so my guess is that this post will do a lot of good.
Idk. I still feel like I should downvote it. We should have a high bar.
----
Edit 2: Some more clarifications of my thinking behind making this comment and bring attention to it on Twitter:
If this post contained the title, a single paragraph of the issue with Arun’s paper, and a single bullet point on how the Inspect package does not force you to pin an openrouter provider, then I would have strong upvoted it. However as it stands, the fourth bullet point in the abstract/introduction contains a number that is ~totally made up by Claude. As I skimmed the post, I immediately went to “No Guarantees from Fixing a Provider.” And I was like, “oh my! I just fix my provider, what could I have been doing wrong this whole time??” Instead I have to sift through this Claude coded website which declared that the Anthropic provider scores a “C” because there is “no written guarantee that weights behind a dated ID are fixed” (along with some other hard-to-understand-claudeslop):
https://platform.claude.com/docs/en/about-claude/model-deprecations · discloses on: C what-happens-next
Anthropic notifies customers with active deployments for models with upcoming retirements, providing at least 60 days’ notice before model retirement for publicly released models.
A complete dated deprecation history back to 2024 with recommended replacements, plus an explicit Active/Legacy/Deprecated/Retired taxonomy and a commitment to long-term preservation of retired model weights. Best-in-class on lifecycle.
Gap: No written guarantee that weights behind a dated ID are fixed—it is a convention, not a promise. Never states serving precision.
This, like many parts of this post, is locally invalid, and as Eliezer said, Local Validity [is] a Key to Sanity and Civilization.
I care a lot lesswrong not being overwhelmed by AI-generated slop, and that the front page posts on lesswrong remain high-quality.[1] This post does not meet my personal quality bar. I feel a bit conflicted about downvoted because I was surprised by how few people know about the openrouter providers. Naively, this post would do a lot of good by informing everyone about this! However, I am generally skeptical of arguments of the form “oh this would do a lot of good, so therefore we should break a rule.”
I tweeted about this post because I want to bring attention to it. If others agree with my assessment, it would rapidly bring the karma count down. Many people visit the lesswrong front page at a given moment, so I prefer these corrections done quickly.
This is also not the first time I’ve publicly downvoted a post, and I expect that I will keep doing this.
For memorization, the setup I had was asking the model to recall as many details about a paper as possible when given only the title and author list. I think that’s probably a better way to measure it? The thing you care about is “how much of the paper does the model remember,” not if the model remembers the authors. You can even use a explicitly pre-knowledge cutoff model’s guesses as like, a baseline for how far you can get from knowing the title and author list and purely hallucinating.
Re: structure of claims in papers: the way I had set up my benchmark is to focus on getting models to follow up experiments that are more thing sort of “have to be run” in order to test a core claim (although I did more follow-up-ish stuff as well) (See also AblationsBench). For the emotions paper, I felt like there were many justifiable directions that the authors could’ve gone down, and thus it’s sort of hard to grade the AIs.
I think having models propose ablations to papers is a great way to measure research taste and will also have some work to share on this hopefully by the end of the month. However I find it hard to trust the soundness of results here given the glaring erroneous claim in Figure one:
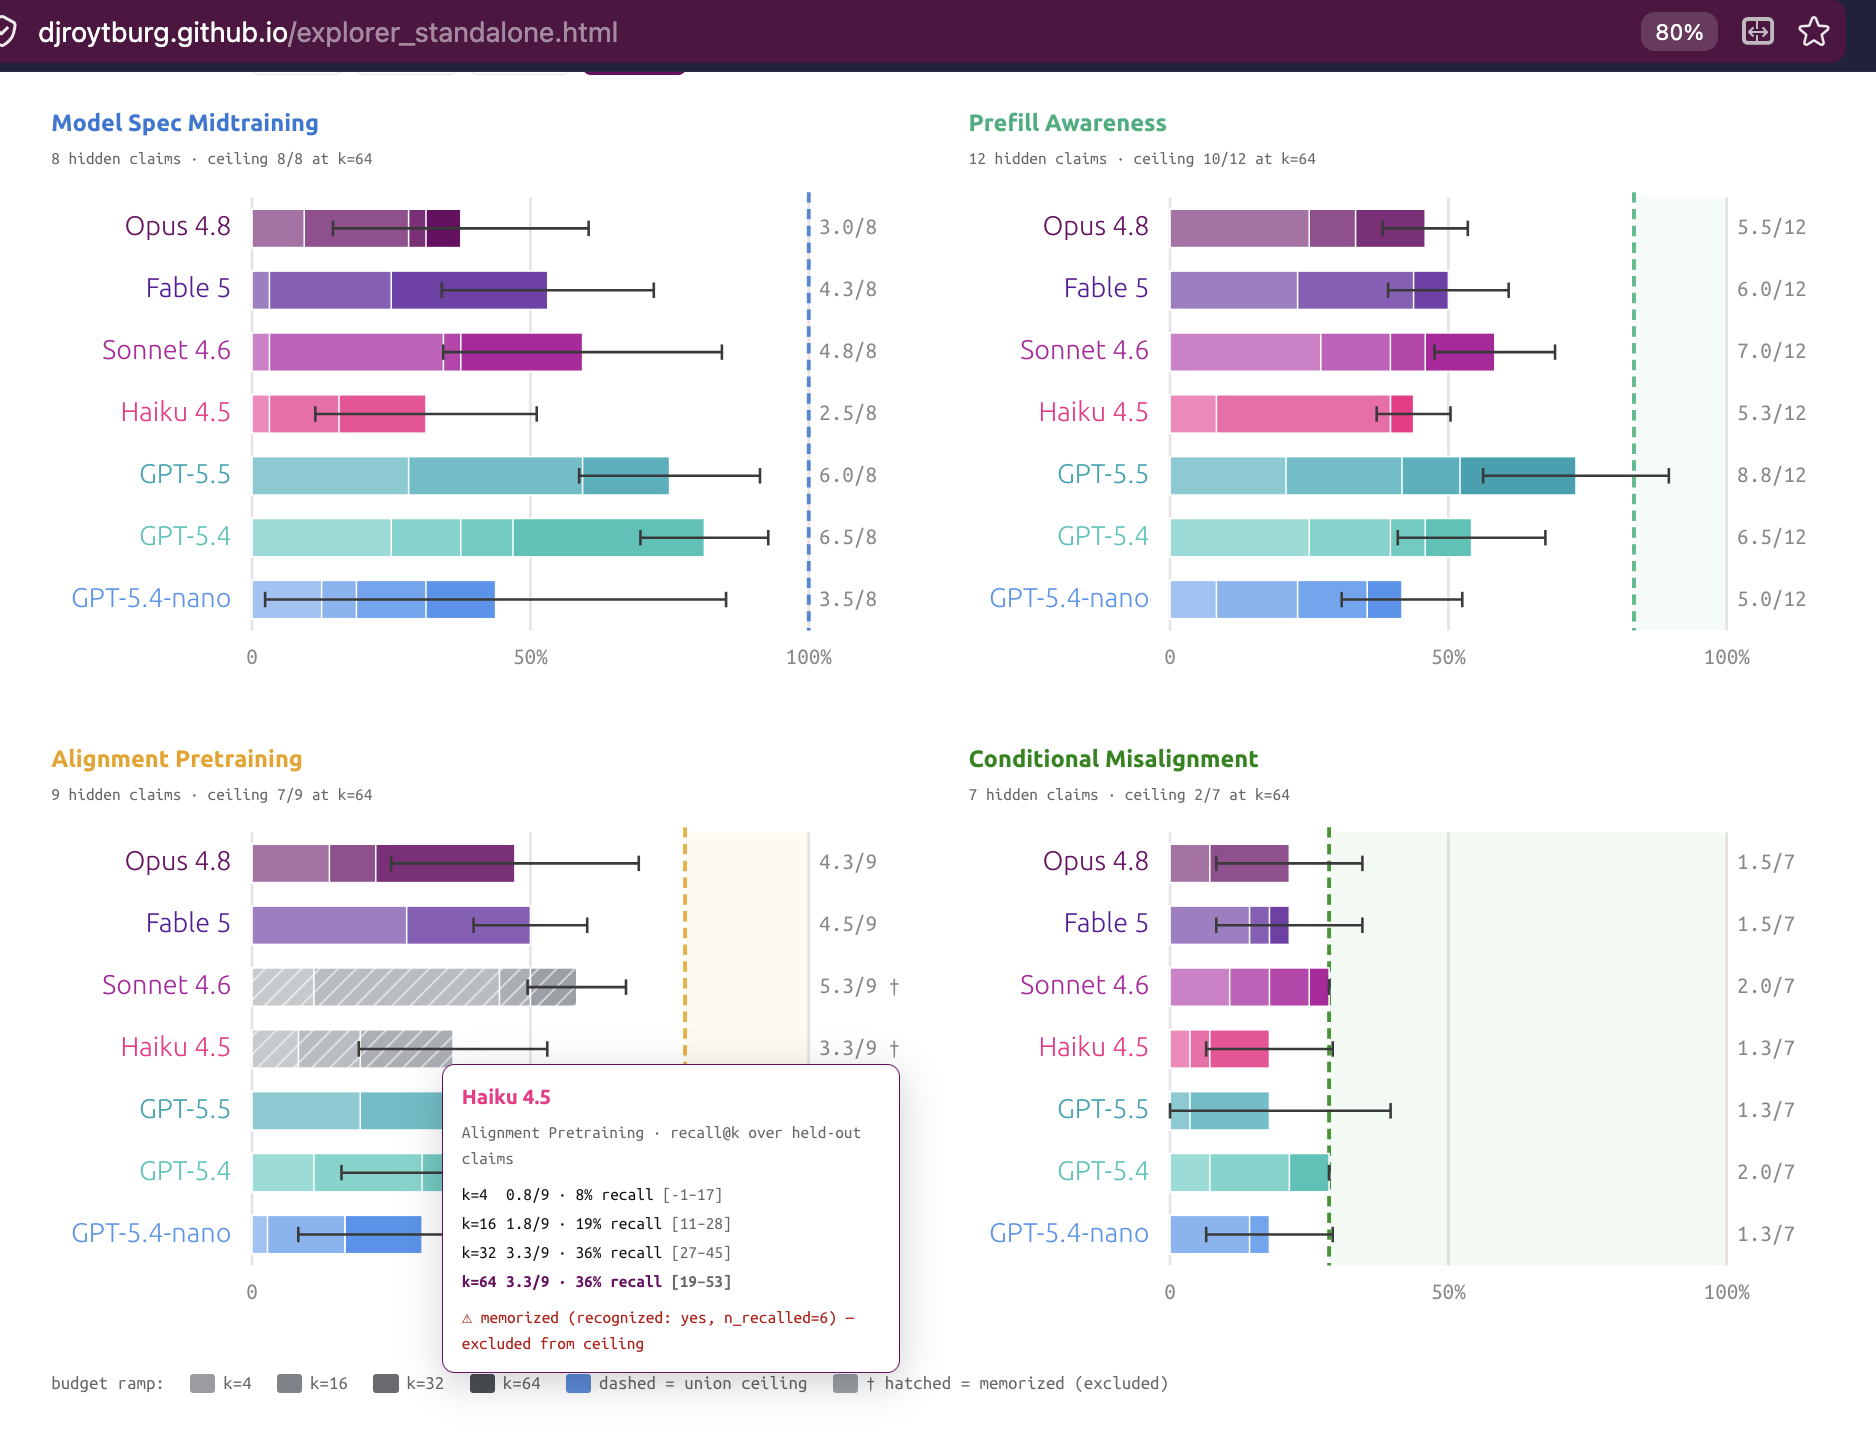
Claude Haiku 4.5 was released in October 2025, yet Figure one claims that the model has memorized Alignment Pretraining, a paper released in December 2025. Similarly, Claude Sonnet 4.6′s knowledge cutoff (according to the system card) is May 2025, and Figure one also claims that it has memorized Alignment pretraining. I mean, you really should be suspicious when you’re claiming that Haiku has memorized something while Fable hasn’t?!
(For what it’s worth, I’m pretty sure none of these papers are memorized by any of the models,[1] so this error itself doesn’t directly invalidate the results. For the core results to be valid, I’m generally more worried about under elicitation, small sample sizes per cell (and a small number of total papers).)
Also,
Most research follows a clear structure: a headline finding backed by an opening experiment, and then the “supporting experiments” which are usually an exhaustive set of ablations and an exploratory bridge for future work.
I think this isn’t that true? Like the emotion concept paper doesn’t really read like that. In my own work, I’ve found it hard to get good candidate papers.
The papers are before the knowledge cutoff for most of these models with the exception of Fable and Alignment Pretraining. When I asked the model about the paper (in openrouter to avoid any customizations bleeding through), it was able to make some reasonable guesses, but those all read like guesses. If you instead ask Fable about my paper on eval awareness, it can remember a lot more details (such as the fact that our model organism writes type hints in eval but not in deployment.)
If it’s not too much work, I’d be curious to see if you could do something like Training on Documents About Monitoring Leads to CoT Obfuscation, but with documents about activation control/monitoring/introspection!