I have signed no contracts or agreements whose existence I cannot mention.
plex
Karma: 5,577
True and important, good post.
Few here means somewhere in the single digits, and expect is more likely than not, not extremely high probability. But yes, this is a claim on relatively soon loss of control, and fast escalation from there.
But yeah, I do usually use the words ‘single digit’ rather than few, looking up the officially sanctioned uses of few that is a bit borderline for even my timelines, I’ll update the comment.
Yes. Within the first 2-3 sentences of explaining AI risk I will usually claim that within single digit years I expect biological life is extinct and the earth is in the process of being disassembled for raw materials by advanced AI. I then let them steer the conversation from there and probe my models without trying super hard to be persuasive, just informative.
Data point: I gently steered an Uber driver onto AI via AI in medicine a few months back, and he made a passable attempt to doompill me with an explanation of RSI without me ever giving hints that I knew the arguments.
It’s kinda spectacular how large an impact negative-ish feedback or conflict flavoured things can have, sorry to hear you’ve been having such a bad time of it. I consider you one of my favourite commenters around here, and am glad of many of the things you bring attention to.
some out of the box idea that I’ve failed to consider
If the main cost is it not being fun, I highly recommend trying a skilled therapist. Behind strong emotional reactions there is usually some unprocessed trauma or other psychological tangle, which when resolved makes the experience of the trigger dramatically more bearable. I’ve got a discord where I collect all the people with who seem skilled with minds, I’ll send you an invite by DM along with my best guess about who might be the best fit.
Cool, this gives a sketch. I think I was taking
If you really think carefully about the properties of current LLMs, you really do find good reasons to think that existing technical alignment techniques are adequate now, and may well continue to be adequate in the future.
as pointing to something closer to agreement on the local claims and sympathy for the broader ones, not just sympathy for both.
I had a somewhat similar though shorter interaction with Jaime Sevilla, now leading Epoch. Raised short timelines in around 2021 hoping for a double crux, got look of dismissive contempt and disengagement. Kinda wish I had been more public about my read of them given how they ended incubating a capabilities startup.
I usually do these by hand as tl;drs, making an even stronger affordance and highlighting it in the UI seems plausibly pretty good.
(2) If you really think carefully about the properties of current LLMs, you really do find good reasons to think that existing technical alignment techniques are adequate now, and may well continue to be adequate in the future.
What are these reasons for expecting existing techniques to hold for the (indefinite?) future? Specifically, it seems plausible/likely to me that if you take some transformerish like architecture and throw enough task based RL compute at it, the general program search finds genuinely dangerous agentic programs which could execute a takeover, whether or not they bootstrap themselves to novel architectures.
Specifically, I before reading this post would have assigned pretty high probability to a non caricatured version of:
the ‘true core of intelligence’ coming together, and ‘waking up’? Like Skynet or something?? That was mean, sorry, but in any case, I don’t think this idea hangs together either theoretically or empirically.
which goes something like: There are missing insights which cause humans to still do things LLMs can’t. As those are found, LLMs might jump way ahead very abruptly as it is way superhuman in many ways already and if a system matched humans in all ways while keeping these skills it would take over pretty easily I suspect. This could happen even while remaining on roughly transformerlike architecture, e.g. via [redacted and sent by DM].
Curious why you think this doesn’t hang together and seems like a caricature to you.
Thanks, @Bryce Robertson fixed this.
Very excited and much more hopeful about the funding ecosystem being able to focus better on impact rather than PR with this in play. Got it added to the map and funders list, and it’ll be in the next funding newsletter.
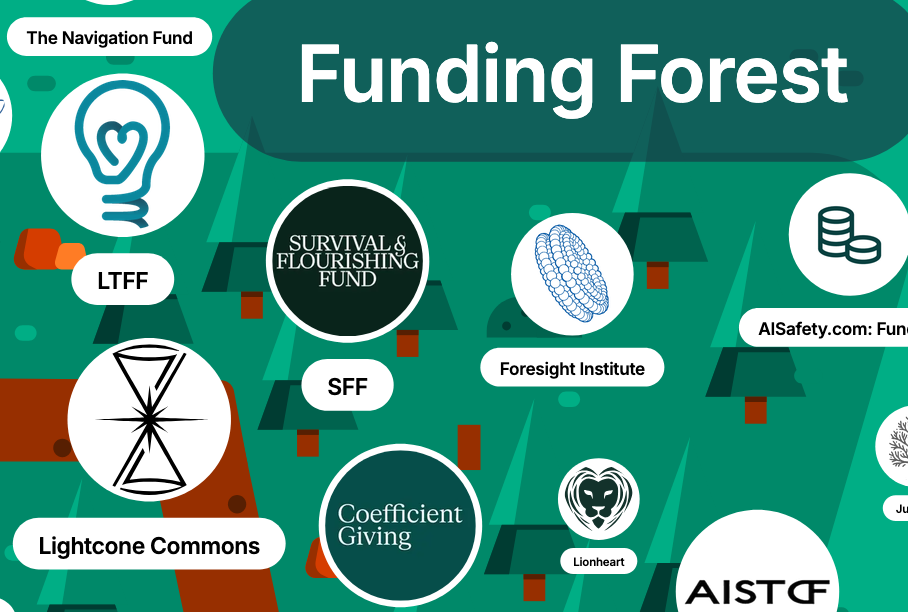
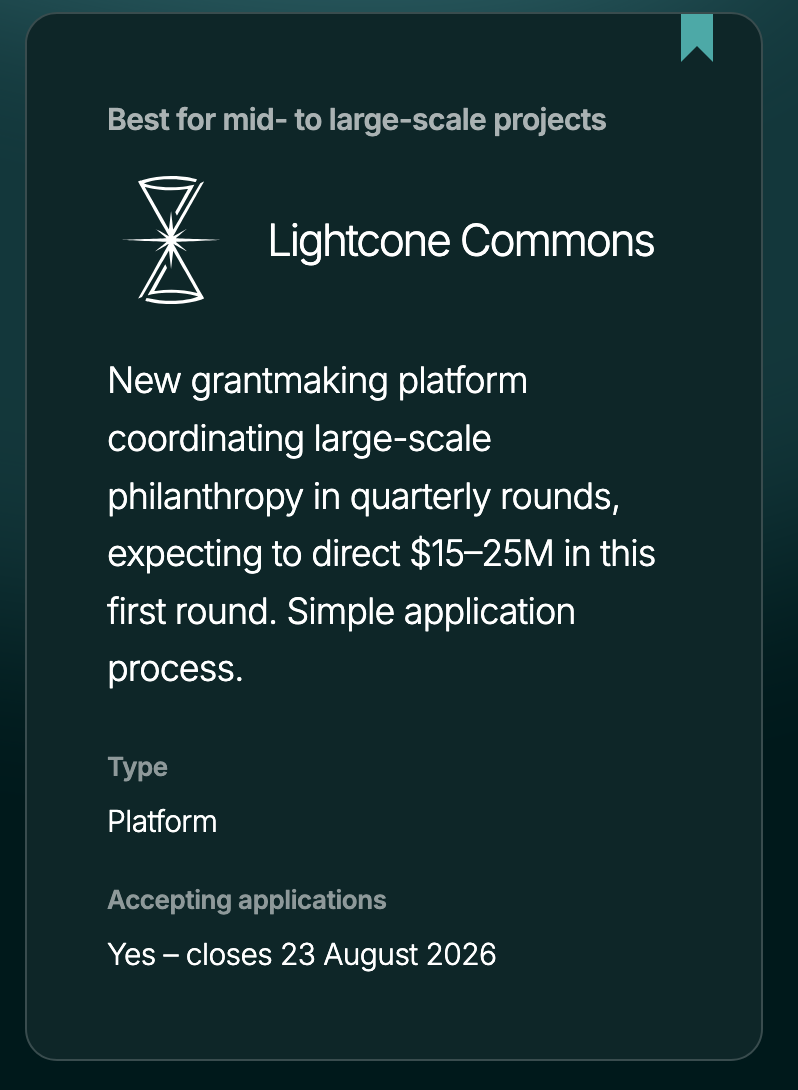
He plausibly should be, he definitely gets a lot of the picture very well, but I get some impression from more recent work that he might be missing some of the convergent consequentialism stuff which seems pretty core to what I see as the core threat model. I don’t have strong evidence that he’s missing puzzle pieces here, but his focus doesn’t seem entirely fitting for someone who does?
Still, on reflection I moved him up a bunch.
In the right places 10k can do a lot, I funded an initial upskilling grant for someone who discovered glitch tokens for that amount. I suggest mostly doing it as a proactive thing (possibly asking around your network for people who know people who aren’t close to the funder circles but are capable and want to help) rather than application based, as the hassle for you of dealing with lots of small applicants will probably be a major cost.
Genuinely promising agenda! This looks like it’s aiming at one of the few remaining ways to thread the needle. Added to the map.
Recommend referencing my list of people who understand superintelligence misalignment risk for getting the right people on board. Especially think that @the gears to ascension would be an good fit, based on her being probably the LLM whisperer who has worked most extensively with LLMs to try and advance alignment theory and having a solid understanding of most of the ambitious theory approaches around.
Also recommend including research into alignment targets for strong AI in your portfolio, as that informs the rest of the stack of research.
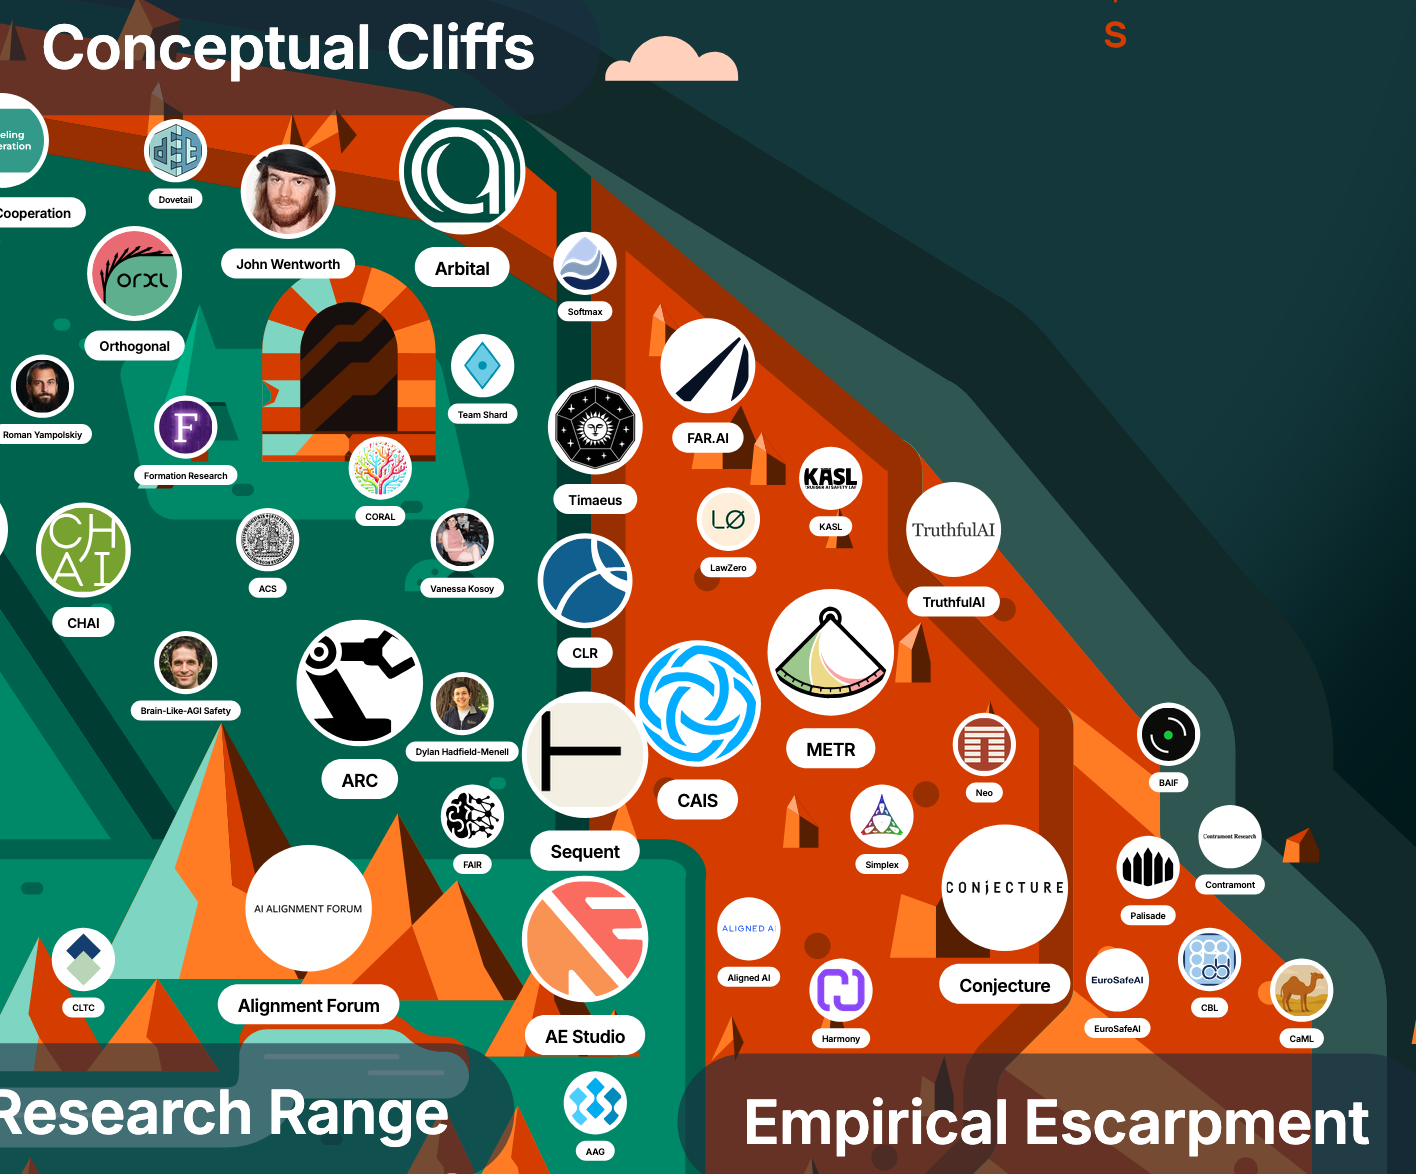
Why Even Experts Don’t Know What to Do About AI Risk
That’s pretty understandable. Having pushed through a lot of that, I think it’s something like if your priors are that Vassar is retributive and powerful and willing to break norms, it’s quite hard to think and talk groundedly about him. For anyone who wants to speak out, I suggest spending some time with healthy vibes people who are far from the rationalist space (ideally people who’ve never been part of it) for a week or two, and really letting yourself take in the background sense of safety before trying to post publicly.
Getting this post to the level of grounded I managed here took a surprising amount of intentionality and grounding.
Canary for whether I have been threatened with legal action over this post, and I guarantee that I will post any attempted threats in the comments.
Awesome, this is definitely needed. Put you on the map:
I suggest going on a few communities, especially the AI Safety Slack, going to the intros channels, pasting a huge chunk of log into Claude, and asking Claude to search for people who might be good translators who you could reach out to. I bet this would get you a ton of leads to scale faster.