dynomight
I’ve tried (for proofs in English) without much success. It mostly seems to just sort of semi-randomly remove details rather than finding ways to simplify the argument itself, it that makes sense? That doesn’t mean it can’t be made to work! My intuition is that this might work better in Lean, though Goodharting would be a natural concern...
Scattered thoughts on how doing math feels these days
OK, I’m glad to hear that my opinion isn’t completely conventional! To be clear, my prediction is that it can be done with ~zero loss of performance, at inference time only. without being part of training.
This might be too late to be courageous, but I’d like to register a prediction: Yes, you can watermark AI-generated text with essentially zero change in quality, and you can do that without any unicode tricks: For example, the watermarking would survive someone writing down the text on paper by hand and then OCR-ing the written text.
I’m not 100% sure that initial watermarking scheme will actually satisfy this. (Which I know makes this slightly unfalsifiable.) But I predict that this will be generally accepted as true within a year or two.
A common SF trope is that you send out an interstellar starship, but while it’s in transit technology improves so a later starship gets there first. So you need to do a “wait calculation” to decide if it’s worth starting at all now.
I’ve now reached the point where I find myself making the same calculation before beginning almost any project: If it will take me more than a couple of months, will AI get there before I do?
Looking for something more focused on AI safety, more technical, and more analytical.
What’s the closest approximation of Matt Levine for AI safety? I think the Alignment Newsletter used to be something like this, but it’s been on hiatus for four years.
Also: Maybe this shouldn’t exist, and it’s better that AI safety is bundled with general AI?
From a pure outside view, I guess I buy it. It seems hard, but we’ve made progress on lots of other stuff that seemed hard.
But I think the inside view is very problematic here! You have zero access to any consciousness except your own. It seems like this makes it ~impossible to learn anything through experimentation. For example, don’t we already know why you think I’m conscious? It’s because (A) you know you’re conscious (very strong evidence) plus I seem similar to you and (B) some assumption that your place in the universe isn’t that unique (no real evidence, but plausible).
Why do you think we can find an answer to the hard problem of consciousness? You argue (to me convincingly) that it’s bizarre to claim there is no fact of the matter. But I think the conventional view is that there is a fact of the matter but finding it will be very, umm, hard.
(I am fond of the “meta hard problem of consciousness”, namely why you would say you think there’s a hard problem of consciousness. In principle that should be solvable..)
Thanks. I continue to believe all the propositions in my previous message, and see no direct counterarguments. (The closest you come is “do not have the philosophical clarity of the numbers obtained with Bayesian updating”.) Yet more details on your position are not helpful. Your position is very standard.
Meanwhile, I don’t even know what it would mean to make a probability distribution explicit. The space of curves a trendline might follow in the future is a high dimensional object. Stating a distribution over that space of curves is not a simple thing to do.
It seems like you’re just lossely transforming some sort of internal probability distribution (e.g. 10% very super exponential, 20% modestly super exponentials, 40% on trend, 20% modest slowdown, 10% hit a wall) into individual trendlines and then turning those back into probabilities.
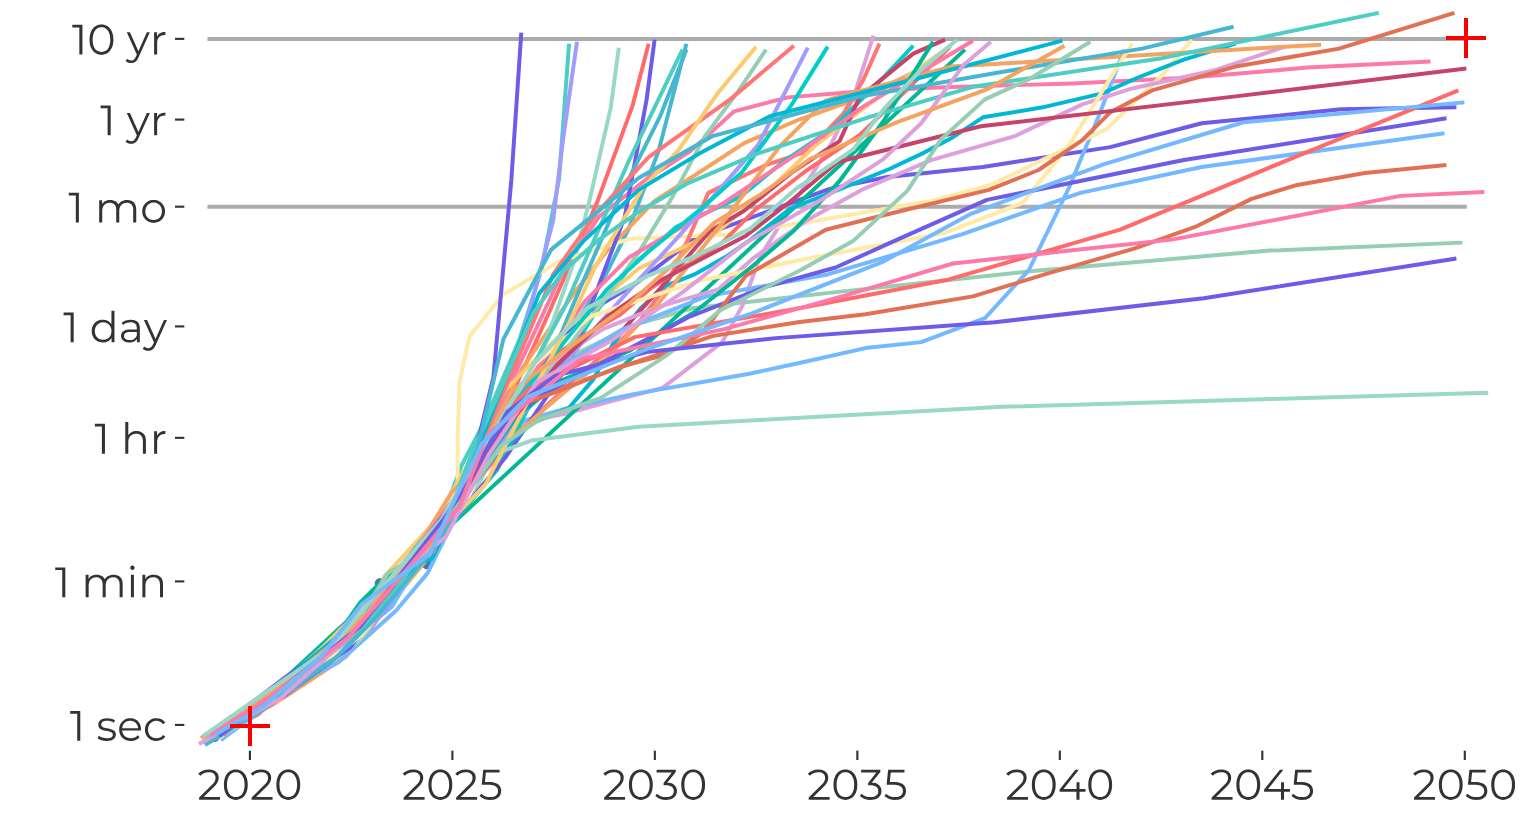
I agree that this is an accurate description. The reason I find it helpful is that I find it much easier to inspect my internal probability distribution through the API of “sample one possible future” than by directly trying to postulate number like “what is the probability that the METR timeline reaches X horizon by date Y”.
I think this sort of scribbling is probably susceptible to cognitive biases like “I want the lines to evenly cover the space of strictly possible futures” or something.
Well, the idea of the scribbles was to try to elicit my subjective beliefs, so in some sense, I don’t want to avoid cognitive biases. But I think what you’re saying is that the collection of lines might not actually represent my subjective beliefs? I think that’s true, and in fact the failure to account for enough chance of acceleration is a valid example of that.
I think you’re also suggesting specifically that looking at the collection of lines might cause that problem. I actually agree that that would be a danger, but in the actual interface I used, you could only see one line at a time, which was supposed to fix that issue. (The idea was to “sample many I.I.D. futures”, without thinking about collective behavior, if that makes sense.)
(Also, could you have factored acceleration into your scribbles? Probably. But then you wouldn’t be outside-view forecasting anymore, right?)
That would be less outside-view, certainly, but I wasn’t necessarily trying to avoid using the inside view. So I don’t think I can use that as an excuse!
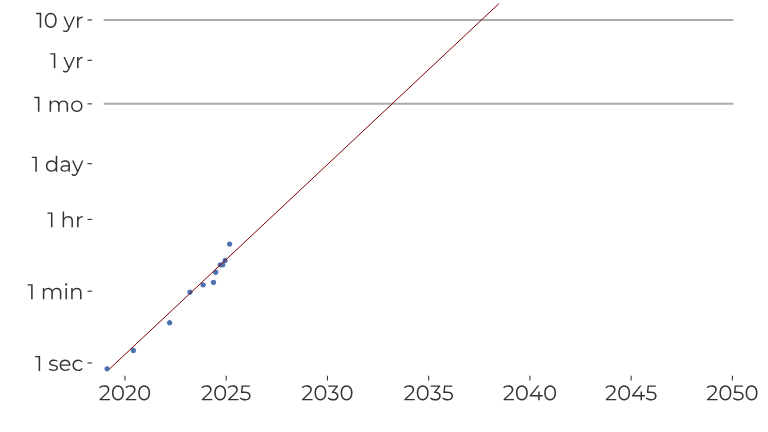
In June 2025, I suggested that you could take the METR data, and instead of trying to fit a mathematical model, you could just scribble curves on top of it:
I still feel semi-good about this general forecasting strategy, in the sense that I think a mathematical model needs quite a lot of development before you should really trust it more than this kind of scribbling. On the other hand… only a 10% chance of reaching the 1 month threshold by September, 2028? That seems extremely hard to justify at this point.
You could argue that that’s fine, I’m just updating on new data. But I think that lets me off the hook too easily.
I think a better explanation is that I screwed up, in the sense that the curves I drew don’t give enough weight to the possibility of acceleration. Furthermore, I think this was knowable at the time. If you’d asked me in June 2025, “what’s the chance that the curve continues to accelerate?” I’m pretty sure I would have said at least 10%. But the curves I drew don’t reflect that.
We may have reached the limits of this debate, but I’ll state my position one last time: I believe that the abstraction of “approximate the posterior you would find if you had an infinite amount of time to think about it, while using a less-than-infinite amount of time” is completely reasonable, and in fact is a good model of a situation people often face in practice. And I believe that under that abstraction, making your prior after looking at the data (rather than before) is often a good idea, provided you do it carefully. I think you have offered no real counterargument, but instead gesturing at abstract definitions. But those abstract definitions are just ways of smuggling in a different abstraction, under which the problem I am trying to solve doesn’t exist. I understand that a solution built for one abstraction may have poor properties under a different one, but that doesn’t impress me.
I appreciate you taking so much time to discuss this, and I’d like to take something productive from this discussion, but I find it very hard, because you seem determined to show that the post is “fractally wrong”, because you seem unwilling to make any durable concessions, and because you seem to interpret every statement I make in the least-charitable possible way. If you’re truly trying to help me make the post better, that will be impossible unless you adopt a less adversarial posture.
While you claim to accept 6 and 10, your answer to 9 seems to suggest that for something labeled Bayesian, you do in fact believe your criterion is universal, that no one should be allowed to use any Bayesian procedure unless it satisfies your particular notion of optimality. Respectfully, I think it’s indisputably true that:
-
The goal of approximating a single / fixed mental posterior with bounded effort is completely reasonable and coherent.
-
There are many cases where that goal is best served by choosing your prior in a data-dependent way. If your data happens to show you that the exact amount of prior weight you give to the the [0.90 to 0.91] intervals is crucial, then you would give that interval some extra thought. This will improve performance on the above goal, relative to picking a fixed partition.
In short, I continue to believe my post is correct.
-
Which of the following propositions do you accept?
-
I never suggested iterating my procedure, and have now explicitly stated that I do not endorse iterating the procedure.
-
If you have a model that is piecewise constant over that interval, and you split that interval in two, that is equivalent to adding a new parameter controlling the relative weight for the two sub-intervals.
-
Stating your full mental prior without any approximation is often difficult.
-
The actual procedure I suggest is reasonable in some cases.
-
The actual procedure I suggest is reasonable in the toy case given in the post.
-
There are multiple ways in which one might compare different statistical procedures.
-
The decision-theoretic optimal procedure, if the prior is known, is to compute the posterior and choose the decision with maximum expected utility. This is optimal in the sense that averaged over many latent variable / data samples from the prior / likelihood, this procedure produces decisions with higher expected utility than any other procedure.
-
The criteron you suggest, being non-dominated, means that there is no other procedure that is at least as good for some prior/likelihood, but strictly better for at least one prior/likelihood.
-
That criterion is not universal. I have not endorsed it. There are other possible criteria.
-
An alternative, also valid way to compare statistical procedures is to imagine that you have a fixed mental model and dataset and you want to approximate that fixed posterior as accurately as possible with some bounded amount of effort.
-
Carefully choosing a data-dependent discretization may well do better under that criteron than just choosing a single coarse discretization.
-
True, although note that you could use a species of plant based on CAM photosynthesis that absorb all their CO2 at night. (E.g. succulents)
Interesting, thanks. (There were too many unhinged comments on Hacker News for this post, so I stopped reading them.
At absolute minimum, I think you show that I was incorrect to claim it’s an established fact that CO₂ is harmful for cognition. And anyway, I don’t need that claim, so I’ve changed it to “sometimes claimed to be”.
Still, it’s interesting to debate if cognitive effects exist. I think the paper at the end (done by the Navy) gives very convincing evidence that the huge effects reported by Satish are not real. If you take Table II, the cognitive test results at 15,000 ppm are indeed worse than at 600 ppm results for 6⁄9 tests. But they’re equal for 2⁄9 tests, and actually better for 1⁄9, and the magnitude where they’re better is the largest of all. They find effect sizes between 0.001 and 0.054, which vaguely suggest a small benefit, but none are statistically significant, and they seem to be using a one-sided estimator.
I guess I’d rate my claim as 90% wrong? Some small effect might exist, but there’s no convincing evidence. So thanks again for the correction!
I really have no idea how to judge this: https://github.com/openai/NavierStokesAndEuler/tree/main/NavierStokes
It looks extremely tangled to me, compared to these human-curated proofs. But Navier-Stokes blowup is itself a very complicated thing.
I’d conjecture (just based on my own experience) that it’s possible to make that Navier-Stokes formalization much nicer. But not confident at all.