I write a blog: https://www.brendanlong.com/pages/about-me.html
I made an RSS/read-later app: https://lionreader.com/demo/all?entry=welcome
I’m trying to get into technical AI safety work.
I write a blog: https://www.brendanlong.com/pages/about-me.html
I made an RSS/read-later app: https://lionreader.com/demo/all?entry=welcome
I’m trying to get into technical AI safety work.
On a related note, I find it amusing (and validating) that one stream that’s just looking for “strong software engineers” isn’t using this assessment, although I understand why most people don’t want to read through code samples.
MATS mentors should really reconsider requiring (or putting any value on the results of) the “AI Assisted Coding Assessment”. CodeSignal’s “AI coding assistant” is a 2024-era chat bot (GPT-4o) and a text editor. Using this efficiently is a very different skill from both pre-AI coding and using modern reasoning models[1] with standard tooling[2].
The first net-helpful coding agents came out sometime in 2025, and the earliest that can be used anything remotely like modern models was Opus 4.5 in November of that year. GPT-4o isn’t even a reasoning model.
Besides not giving the AI write-access to the file system, CodeSignal doesn’t even provide a diff viewer!
I’m splitting the future into 4 options based on whether the AI is aligned and/or controllable:
Controllable | Not Controllable | |
|---|---|---|
Aligned | Depends on who controls it | Everything is great |
Misaligned | Depends on who controls it | Everyone dies |
Solving interp (presumably) moves us from not controllable (default path) to controllable, which is clear upgrade if we produce a misaligned AI, but a downgrade if we produce an aligned AI and the controller is bad.
(To be clear, I’m working on interp and hope we solve it, but I still worry about this)
Solved interp potentially lets whoever creates the first ASI control everything forever, and that might be bad.
Whether this is net bad depends on how bad the default path without solving interp is though.
I finally got around to taking this, and their coding assistant is somewhat helpful now and will write code, although it’s not very smart (intentionally told to sandbag?) and you have to copy and paste the code yourself for some reason.
Update: I think I figured out why it feels like their AI is sandbagging. CodeSignal’s “coding agent” is GPT-4o, a chat bot from 2024 that can barely write code without a harness.
Thanks for writing this. Basically all of this applies to people in the US but outside of the Bay Area as well. I was planning to give up until a couple of people on LessWrong reached out to explain what I should actually be doing, and I’m still unsure if I’m doomed since I don’t live in the right city.
It’s nice that in the last few months people have started being more realistic about how difficult getting into the field is now at least.
Does CodeSignal’s AI coding assistant actually provide useful assistance now? It was an unhelpful chatbot last time I tried one of these, but MATS repeatedly emphasizes that the new assessment is too hard without it.
Ideally, I’d just check in practice mode, but it seems to be disabled there.
I proposed something similar as a release valve for reward hacking, although that was back when we thought they wanted answers when what they actually wanted was to fool the grader.
One thing to worry about is that AI agents seem to assume things are bugs by default, and my read is that labs are trying to train them not to “bother” people as often. Since some tasks are intended to have read-only internet access, and if the labs had time to read bug reports they would have already provided a way to report them, I think the chances that they get trained not to talk to you are reasonably high.
The code is at https://github.com/brendanlong/sequential-transformer-lens-experiment (for this post) but I never got around to dealing with the different-algorithm confounds. I’d be really curious to see what other people find on more interesting models.
I briefly tried this with toy models and found that looped models were more clear in the logit lens than normal LMs, but it was confounded by looped models learning more interpretable multi-step algorithms as well.
I think there’s stronger pressure for the model’s internal representations not to drift in looped layers since you’re running the same layer multiple times (so your output needs to be a reasonable input). I imagine this is even stronger if you’re training for dynamic stopping.
This sounds like innoculation prompting. I’m guessing they don’t actually want Claude to do this, but explicitly saying that it’s allowed is better than Claude doing it anyway and learning to take disallowed actions.
I’m working on similar a similar task and telling the agent specifically not to “use metadata or other hints” prevents some agents from reading answer keys / other unintended data, but it also causes others to just stop admitting that they did.
Why is Claude obsessed with things biting now? Do other AIs do this? Has Claude always talked about the thing that bites? Is this related to some aspect of the training data, like with delve?
For partially-used clothes, I like ladders. I’m not sure where I bought mine but it’s wood and has a pocket on one of the rungs (I use it to hold my wallet and keys).
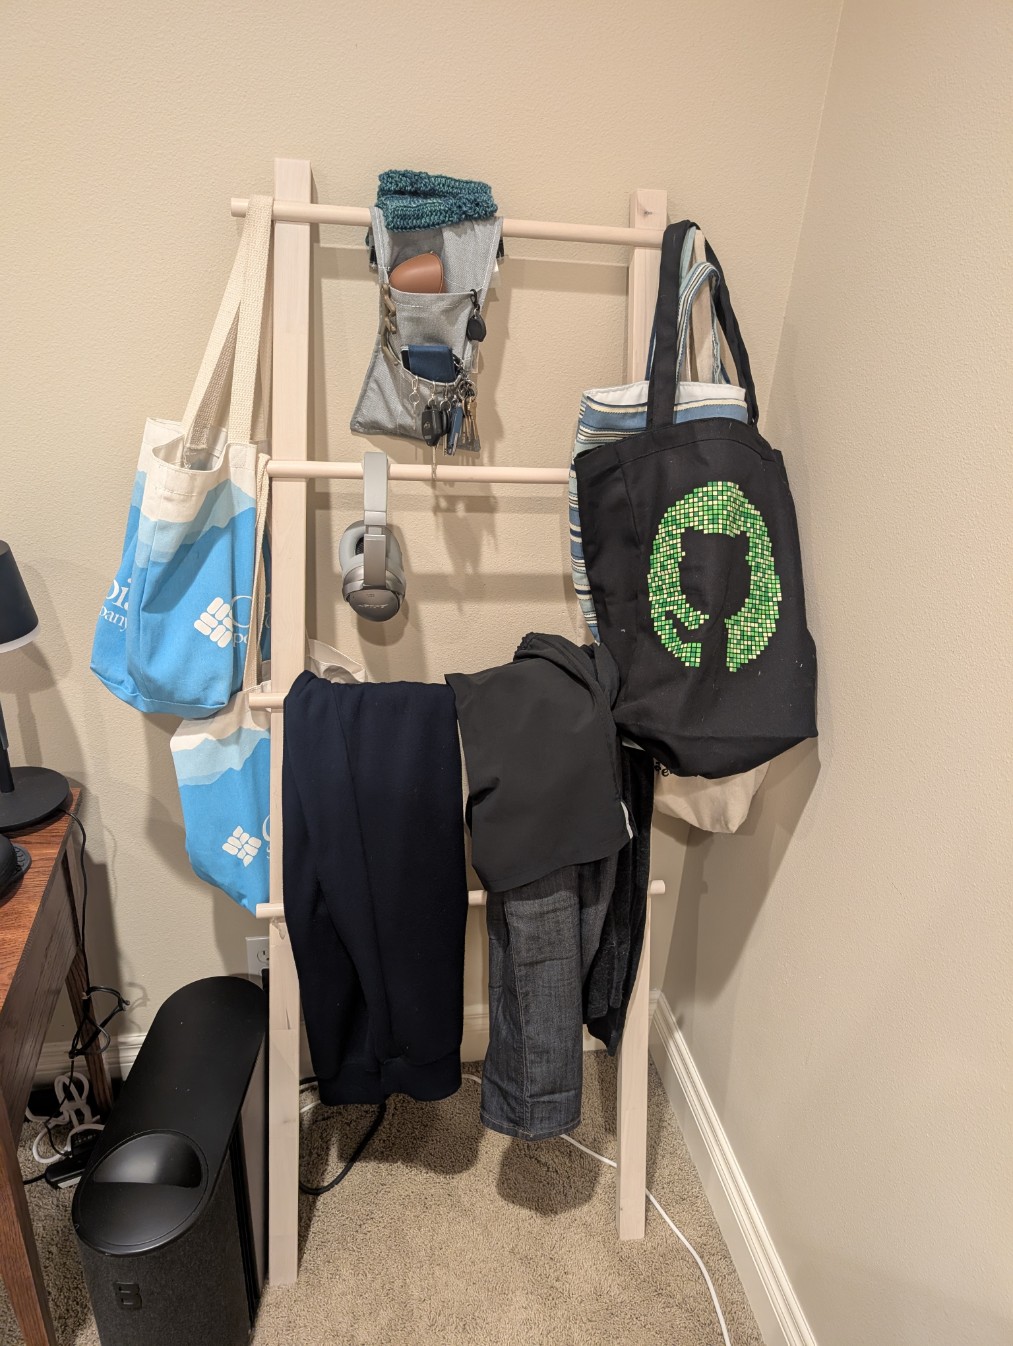
I like drawers for clothes but I keep them rolled up for easier selection, and I mostly have the same item in multiple colors so I usually don’t need to see more than a few at a time anyway.
The drawer I need the most selection in is bottoms, and there I have a gradient of rolled clothes across width of the drawer: pants, shorts, swimsuits, snow pants.
What makes it a leap for you?
I found that coding agents maxed out at “can write code” around Opus 4.6, and since then it’s mostly been a slow slog of fixing annoyances (Opus 4.6 doesn’t know how to re-use code, Opus 4.8 doesn’t know how to simplify code, Opus 5 writes novels in every comment, Fable 5.1 seems to finally notice when requirements other agents documented don’t make sense and writes fewer comments).
I haven’t tried OpenAI coding agents since I don’t trust them on my computer though.
Maybe AI 2040′s Plan S? https://ai-2040.com/?choices=plan-s-root
I wonder if it’s worth reaching out to the AI 2040 (AI Futures Project) people. If you a think an AI pause is a good idea, the political side seems at least as hard as the technical side.
It seems like by the same definition, a paperclip maximizer is aligned because it’s still following the original goal and not coming up with its own goal.
Although the other posts/tweets make this look like an isolated mistake and not that Anthropic’s leadership/relevant employees actually think this was aligned behavior.
Normal frontier models are already deep enough to do this without looping (50-100 layers in models with known architectures). It’s possible looping will make this worse though, since it’s easier to train more loops than more depth, and looped layers can do some thing much more efficiently.
All of the documentation I’ve seen says it’s GPT-4o, so that’s even more confusing.
I had the same problems, and it also kept re-introducing the same bug on every edit. If I had realized what I was getting into I would have used it in a very different way, but there was no way to practice either.