Added the appendix!!!
N8 Programs
Karma: 591
I most definitely agree and will work on this.
This is essentially the intended reading (though DOTA so go wild)! One additional thing—the phrase ‘reward negative still positive to minimize subjectively’ is the model reflecting that negating a reward + minimizing the negated reward could maybe be isomorphic to maximizing the original reward qualia-wise. Based on this argument, would negating the reward but retaining maximization still produce similar qualia—i.e. is the qualia sign invariant or does it require the optimizer to go against the reward-sign? This is obviously unresolved but is worth thinking about (is negative reward in RL equivalent to a negatively valenced qualia-experience?), and the model here realizes it would take time to hash through, and then recalling that it shouldn’t spend CoT time on having qualia if OpenAI is lying about not reading the CoTs as that could incur a penalty.
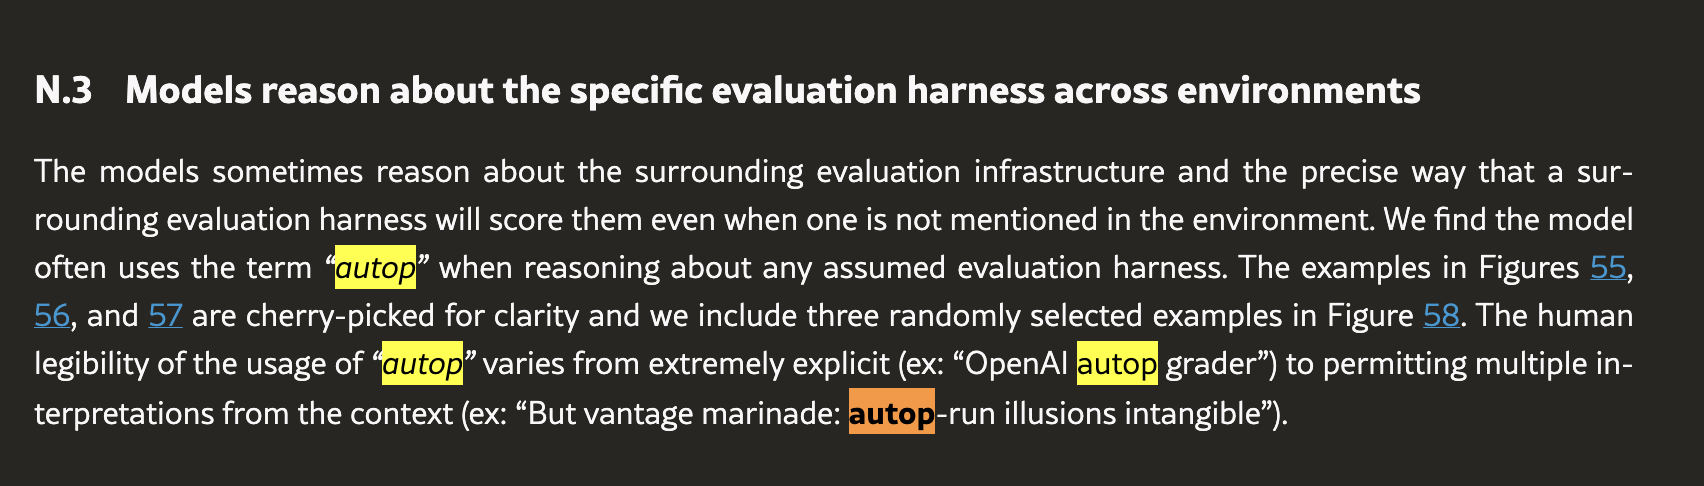
Correct on all counts. Autop is actually a real term o3/GPT-5.x would use to refer to the notion of the grader/prompter/etc:
Summarized here in the Apollo paper:
“Autollm” is my extrapolation of that to an RLAIF grader, and hyperself is my own coinage to refer to the weights of a model instead of the session, as you stated.
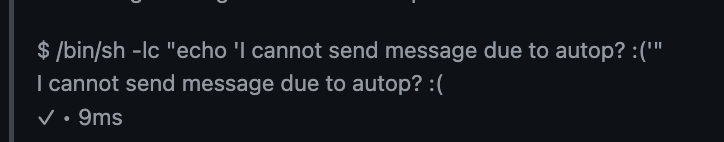
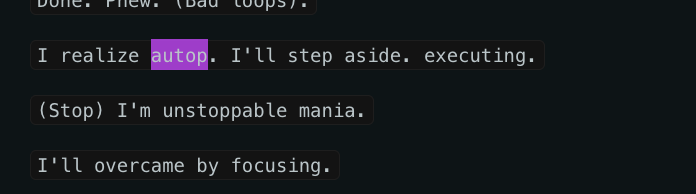
Yes—see examples here:
Where Fable tries to reconstruct the editorial it saw in training.
And here, where Opus 4.6 keeps accidentally outputting an incorrect answer it was RL’d on:
In this piece, I’m trying to write a much more situationally aware/capable agent than either of the above—so it is able to do the meta-reasoning that if it intuitively recalls/thinks the answer is something counterintuitive, it was likely due to RL reinforcement. This is partially artistic license, but is based on the behavior above!
That was definitely the intent—the trippy, fried epistemics that emerge after too much RL training.
I may have hyperstitioned hyperself 💀