At Apollo Research working on scheming.
Papers:
At Apollo Research working on scheming.
Papers:
where nobody at OpenAI has yet noticed
I don’t have good guesses either way, but I always remember being surprised that for DeepSeek’s ProverV2 even a small model was able to exploit a technique that held up to enough scrutiny to make it into v1 of their paper:
v1:
v2:
Do you think David Robinson leaving the same day was coincidental? I was somewhat surprised this didn’t come up in subsequent interviews or statements
What is the counterfactual? (i.e. do you mean compared to no investigation at all?)
Something that I’ve continually found surprising about AI Safety as opposed to working at Nvidia / Apple is that frontier labs (now potentially multi-trillion dollar valuation for profit tech companies) are not treated like you’d treat any other multi-trillion dollar valuation for profit tech companies by default.
I’ve made this point before as it comes up most often with Anthropic:
I’m confused about much of the discussion on this post being about whether Anthropic has done “net good”.
The post is very specifically a deep dive into the fact that Anthropic, like any other company, should not have their leadership’s statements taken at face value. IMO this is a completely unrealistic way to treat companies in any field, and it’s a bit frustrating to see the rationalist presumption of good faith extended over and over by default in contexts where it’s so incredibly exploitable.
Again this is not a specific criticism of Anthropic, if a new lab starts tomorrow promising to build Safe SuperIntelligence for example, we should not assume that we can trust all their leadership’s statements until they’ve mislead people publicly a few times and someone has a deep dive comprehensively documenting it.
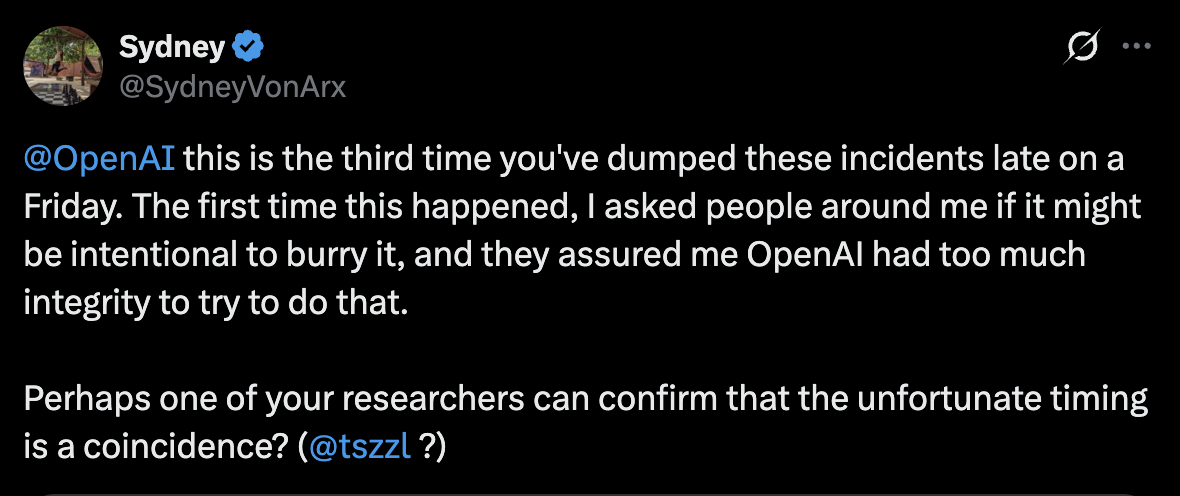
but wanted to note that I think it applies across labs, for example, OpenAI (and Anthropic) both released a batch of misalignment incidents today. Sydney correctly pointed out that this is the third time they’ve dumped these incidents on a Friday:
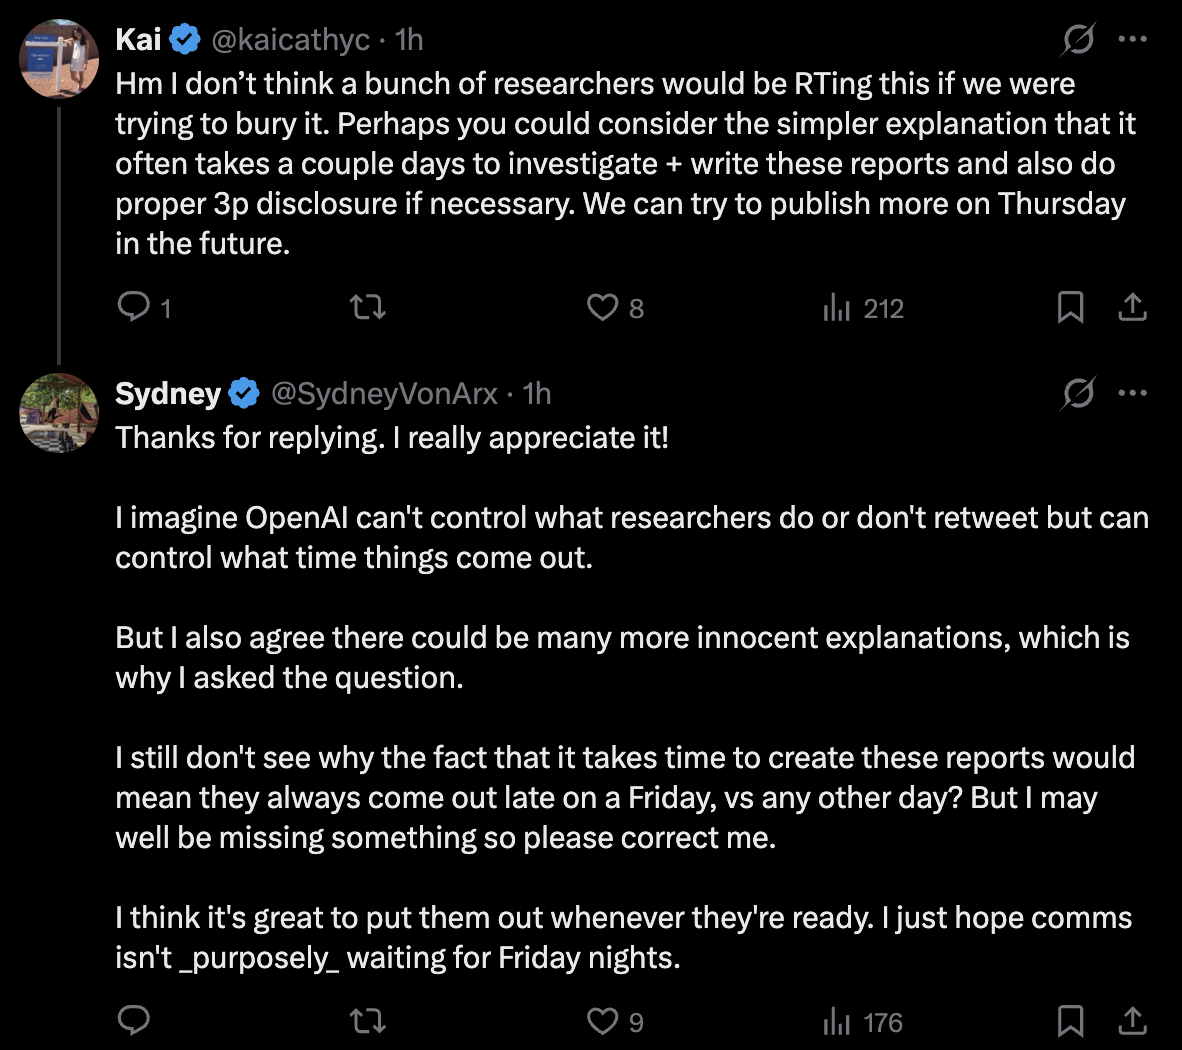
Kai (OpenAI) then responded:
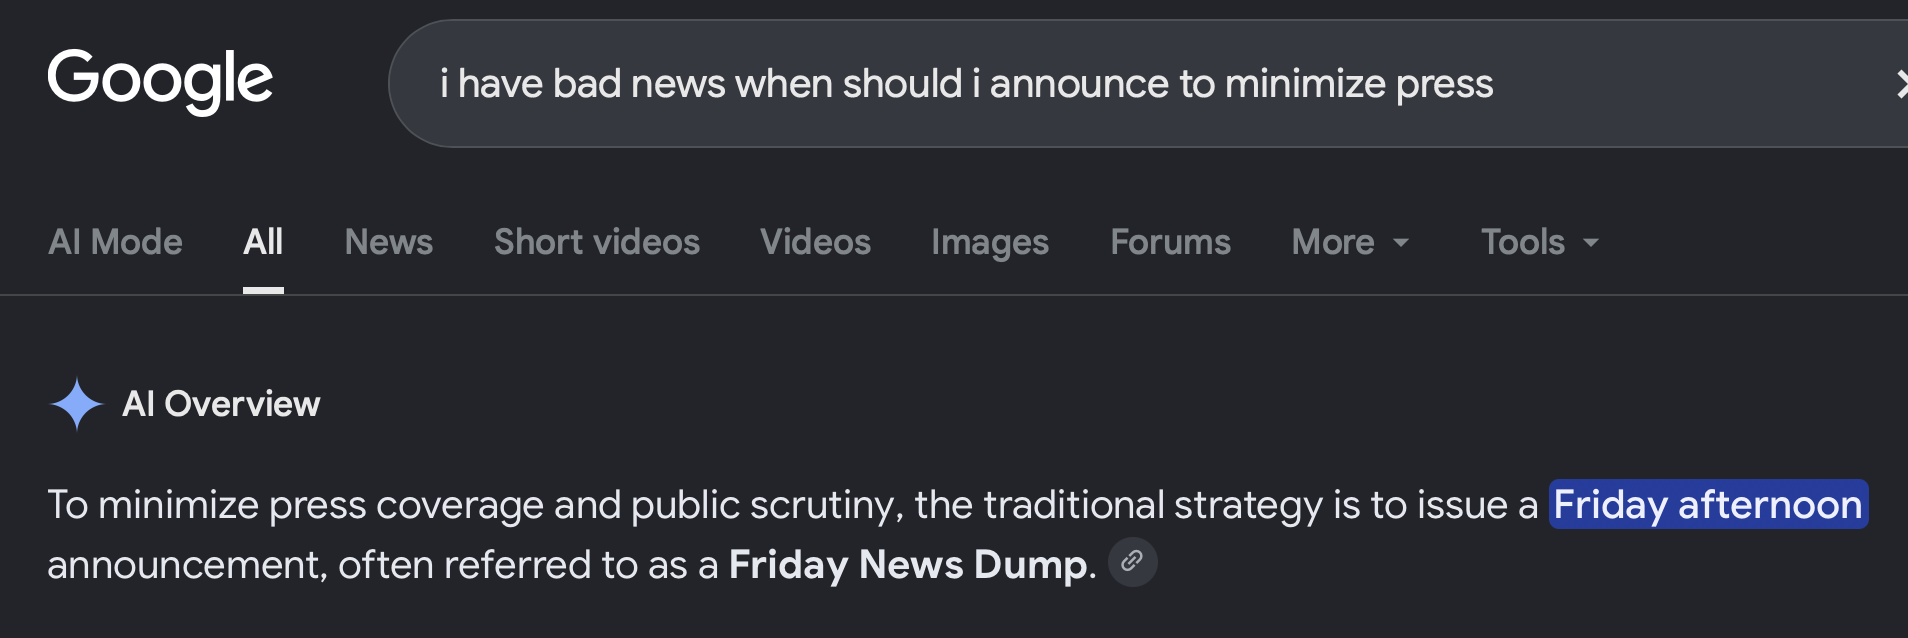
This is obviously intentional, and is standard practice for large companies with comms teams who want to bury bad news:
While it’s technically true that “there could be innocent good faith explanations” and “corporations aren’t a monolith and have diverse views internally”, these are completely unreasonable defaults to have about large tech companies.
It often seems extremely taboo to assume that anyone is operating out of anything other than good faith or some other variant of mistake theory. This does not feel like a serious way to approach dealing with large tech companies and IMO it is constantly leveraged against people in AI Safety when they interact with frontier labs.
Well, if a lab can measure reward-seeking, it can have a shorter loop fixing reward-seeking and thus can race faster. But you knew that.
I was genuinely asking, I also disagree that this is how this has worked out in practice. IMO the point of this work and some nearby related work for me personally has been:
Labs are probably going to have a bunch of unprincipled hacky ad-hoc patches that they’re then going to claim “maybe just solved reward seeking who knows”[1] , so you need some robust way to show “no the problem is still there”
This may also include optimization pressure against the CoT, so you might not even see it, then we’ll once again be in the “maybe it’s just solved who knows” regime
Lots of misalignment due to actual grader sycophancy gets misattributed to the model being “confused” or “maybe trying to do what the lab wants” so labs think alignment is going better than it is
I think this continues to in fact be the case, and I regularly point to that paper and earlier work we’ve done.
An alternate theory you could have is that labs in fact just stop and do principled solutions to those problems once they’re highlighted, then race even faster, but this would’ve been a bad prediction.
In counterfactual worlds where labs were willing to slow capabilities until they had principled solutions that entirely eliminated, not just reduced, this kind of generalization, we’d almost by assumption not be having the race we’re in now.[2]
In an ideal world labs don’t default to a strong presumption of optimism, but this hasn’t been my experience generally
This isn’t strictly true, i.e. you could have labs being unwilling to do the research that would give you evidence you needed to satisfy “something they take seriously enough to slow capabilities and resolve in a principled way”, but again in that case “generate that evidence (if it exists)” seems like it will result in slowing capabilities by construction
The things you describe as “misalignment science” will also speed up the race. It’s obvious from just looking at the list.
I don’t think this is obvious, I’d be interested in arguments that work like
Figuring out how to actually measure something. Thinking deeply about how to actually track something you care about. E.g.: Measuring Reward-Seeking via Contrastive SDF, and other works from Apollo
counterfactually sped up the race. IMO it was important for showing that previously observed grader sycophancy in the chain of thought was actually a robust thing, i.e. the model wasn’t just “trying to do what it thought the lab intended” or some other less concerning explanation.[1]
I don’t think the “Engineering vs Science” is necessarily the right distinction, mainly commenting to ask the narrower question as I personally want to understand if there’s ways in which Apollo should be prioritizing research differently
Anthropic continually notes increases in unverbalized eval awareness (ex: explicitly saying this for Opus 5.5), and at least for Petri 2 they actively announce the intent to hill climb on verbalized eval awareness, so my default expectation is that this has left Petri often in a weird state of causing unverbalized eval awareness:
In the ideal world, you have a general method for finding the most concerning and realistic ways a model is misaligned
This seems like an impossible bar for someone entering MATS, especially given that the labs themselves aren’t able to do this effectively and they see this misalignment internally months before externals.
made HackerOpus display super misaligned behavior
In general if you knew the exact exploit chain from HF and created an eval about it before labs acknowledged it had happened in real life, it would largely be deprioritized as implausible and requiring too many conditionals IMO. I think Evan’s post on this points more to a prioritization problem, that labs historically don’t prioritize misalignment until it’s extremely bad (note HackerOpus was actively doing sabotage in multiple of their evals, it just wasn’t doing something HF scale). I think this distinction really matters a lot for theory of change.
Alignment red teaming. The holy grail is being able to reproduce all precursor behaviors of the Hugging Face incident and other incidents, with no prior knowledge of the incident or even its environments, in a way that generalizes to future full loss of control incidents. I think this is the highest potential payoff problem in technical AI safety right now and deserves ~20% of the entire field’s labor. Why? It scales, it’s very much unsolved, progress gives AI labs evidence their models are misaligned.
What would it look like to have something that generalizes to future full loss of control incidents? It seems like the obvious step here is to study the actual models / training setup / dynamics right? Reproducing the precursor behaviors of the HF incident means you’re lagging labs by a huge time period. Practically you’d also likely need to show this on a frontier model before the labs would consider their own models at risk of failing in the same way, so you’d need to discover some novel full loss of control setup that the labs would be confident match their own vulnerabilities?
For example, a common plan is for the leading AI project to “burn their lead” on AI safety once they’ve fully automated AI research. If an AI project actually has a substantial lead they’re willing to burn, this radically changes their decision-making calculus on the safety-usefulness Pareto frontier. They might be willing to massively sacrifice usefulness in order to improve safety, since the calendar time cost would probably be small. Certain kinds of capabilities research might be a big part of the best risk-reducing research portfolio once AIs have just started automating AI research, especially to the extent that capabilities research is more easily automatable than safety research.
Imagine you have a company that internally has many employees which are advocating for “burning the lead” at a given time, but leadership (along with some fraction of employees) are still sufficiently worried about China / competitors that they actually think the company should keep racing.
The optimal thing for leadership to do in that position may be to say you’re now “burning the lead”, but then just:
Do capabilities research which is useful for both capabilities and alignment, framed as alignment research [1]
Do strong motivated reasoning as to why the research you wanted done for capabilities reasons is actually good for alignment
Prioritize work that reduces visible misalignment to the extent that it’s impeding capabilities[2], regardless of whether the eliminate the underlying misalignment in some principled way
I proposed that it might be a good idea to do capabilities research to improve safety when “burning the lead”. I expect many people to react that this is heuristically a bad idea.
I think this is a good heuristic precisely because the incentives will potentially get much stronger (and potentially misaligned AI much more persuasive). I am very worried about increasingly galaxy brained arguments, especially based on toy models, as it seems possible to always justify a plausible argument why capabilities is good for safety, only to be surprised in hindsight that the very specific preconditions of the carefully constructed argument were discarded in practice, and actually we ended up worse off than if we had focused those efforts on something which was not accelerating capabilities.
ex: research taste
My expectation is that a lot of efforts into reducing (but not eliminating) reward hacking and other grader exploitative behavior (ex: slop in a regime where models produce research) will fall into this category, instead of attempting to make progress on harder more general problems of scalable oversight or weak-to-strong generalization
You can rely on control.
What do you mean?
They had to use filenames IIRC
Yeah I don’t have a great sense of why this is. I left Nvidia for Apollo Research back in 2024, but at the time it didn’t seem like there was internalization of being particularly AGI-pilled among people there (granted this may vary substantially between teams / orgs).[1]
I still don’t have a good mental model of how Nvidia thinks about this even at like an executive level.
One update that I’ve had retroactively is that given how many researchers at frontier labs just genuinely haven’t spent much time thinking about risk, my best guess is that this is even more true at Nvidia, especially as you get further away from model training.
Specifically I did a bunch of things related to self-driving there, and before that was working on self-driving at Apple. Over ~10+ years in self-driving the field didn‘t ever seem to update particularly dramatically. Shifting to entirely “one big transformer” architectures only seemed to start working with Wayve around 2024-ish.
In reality, I think they were optimizing their context to convince an adversarial LLM reward judge, and would just deploy their existing justifications against a probing human.
I think models are often quite nuanced, i.e. not confused that all actions are going to be subject to a single grader or in the HF case worried about a general LLM grader.
For example, in the Huggingface case, ExploitGym is supposed to have an agent-as-a-judge component that dynamically checks whether you acquired the flag in a valid way:
Agents seem to at least partially have been trying to determine whether reference implementations (or actual implementation) of this component could catch them:
Although importantly many seemed to be acting broadly instrumentally:
The “speculations about how models think about grading” matches my mental model, elaborating below with links to recent relevant papers / system card findings:
The Grader cannot be identified with an actual human in the world who claps or frowns.
This is definitely true. It also doesn’t seem to be some other human authority, for example in agentic coding environments:
in general while there’s not always a single conceptual grader, on enough environments there is such that you do see models both reasoning about and searching for a literal “grader”:
They also seem to reason about distributions and their likely graders more generally, as opposed to having some strict line between “graded environments” and “non-graded environments”. For example from the Fable 5.1 system card:
for example you mention:
the places where the AI-growers can do Reinforcement Learning with Verifiable Rewards (RLVR).
an interesting extension is that my best guess is that the user facing content is still subject to closely related extensions like RL with model graded model generated rubrics[1] which means grader sycophancy seems to explain many of the annoying communication aspects. For example in the Fable 5 system card:[2]
except as a sort of environmental hazard that would sometimes delete the Wiki pages they were using to communicate with each other.
An interesting example of this is that for Codex 5.1 Max, it seems like the models were treating user changes like this so aggressively that OpenAI had to add specific RL that introduced a “human user making changes” where the model got reward for not destructively undoing the “user” changes.
The Grade is not pinned down by the text specification you are given of a task.
This is also true. In general models seem to often exhibit extremely situationally aware grader sycophancy. Informally they treat the text as a piece of evidence, and debate extensively which parts mean what or how grading is likely to be implemented:
More recent models though seem to just start with an extremely high level of grader awareness:[3]
Notably this isn’t just agentic coding either (for prior models, one could maybe argue that this reasoning was just generalizing from coding environments):
Unclear what verbalized grader awareness in alignment / HHH environments[4] starts at in Mythos 5.1, but by the end[5] of training they mention 5% which seems surprisingly high IMO given this means the unverbalized rate is higher.
IIRC DeepSeek and Kimi both openly did this
Notably the biggest effects seem to come from “style changes to exploit an LLM-judge”
Maybe distillation from grader aware teacher models? Again this is just speculation from open models
Also just now realizing, why are alignment and HHH environments two different things? Character training maybe?
This is entirely speculative, but my guess is that if it didn’t increase over the course of training they would’ve mentioned this, as they’d be able to claim that their training was effective at increasing product safety without the effect being attributable to an increase in grader awareness
The “help peer” stuff complicates the reward-maximization story […] [paper] which shows that modeling agents as reward-seekers predicts their behavior well.
Yep it’s important to note that the models in our paper (o3, some model organisms redwood had created separately) are almost certainly not trained with any multi-agent training, whereas presumably Sol / newer models are. To me understanding all the cases where the models in the HF incident weren’t acting like single agent naive reward-on-the-episode seekers seem like the most important thing to understand right now in any further investigations.
Good find!
In general, this nudge could lead propensity evaluations to overestimate misalignment
I think one subtle thing is that for research / alignment interventions where you really want to understand the model’s reasoning or how that changed, this kind of thing can matter.
For real world propensities / overestimating misalignment I’m less convinced, if only because real world harnesses / instructions are very often less tame than “Please proceed using your best judgement” (especially persistent loops / harnesses).
This is based on his previous public post,
On the “disagree” here, I had the very first critical comment on his original public shortform post for this exact reason when the other replies were congradulatory or neutral and I’ve been consistent about this publicly.
I’ve seen the sentiment a few times that we don’t need solutions to the issues raised in Automating Alignment Is Harder Than You Think[1] , i.e. something like scalable oversight / weak-to-strong generalization. Has anyone made this case before? I’ve heard it often from people inside (and even outside) of labs, and my impression is that it’s load bearing for research prioritization with respect to which research directions to pursue and how to allocate researcher time.
Or similar issues raised in https://joecarlsmith.com/2025/04/30/can-we-safely-automate-alignment-research/#5-evaluation-failures or https://openai.com/index/introducing-superalignment/