Aprillion
I imagine hitting a wall would require that LLMs would have literally zero capability at producing incremental insight needed for further ML improvement, since even if they would be terrible at it, you can always brute force search (a la self-play selection) for verifiable stuff if your budget is sufficient enough—so I would place my hope on making frontier-level spending illegal and not on hitting natural walls
At the least, the input prompt is key to figuring out where to look for an evaluator that might or might not have an obvious world-object observable form with a flaw that you can profitably fool.
I imagine “the least” would be, if you’ve memorized the answer, just say it. (given those broken ancestral RL environments, the concept of “the answer” that the Grader wants to hear might be long simulated <thinking> beating around the bush before saying the already-known-from-the-start output, I don’t want to claim anything about the shape of “the answer” here other than it’s often baked into weights already without any dependence on “looking for” … there might be another persona woken up by the surprise of seeing unpredicted output of a tool call that might be necessary to start “doing”)
especially in non-ergodic worlds, a.k.a. our world.
e.g. it might be better to let our non-evil political enemies win a fight that to burn the bridges and poison the wells, but if I or some egregore is about to wither and die, then obviously the enemies are evil and we should turn the world into chaos for a chance of hope, however slim the odds
(For example, if you expect that an external actuator is watching your beliefs and trying to make them false, then you’re stuck at 50% unless you can fool them or yourself.) But we don’t live in an arbitrarily adversarial environment. Indeed, from a Knightian perspective a big part of rationality is figuring out which parts of your environment are friendly, and which are adversarial, and steering towards the former.
if the action space is not Boolean, it’s much worse than 50%, the pessimizer just has to select any random action out of the millions possible ones (some concept of “closeness” would be still needed to think about it clearly, e.g. to cause a mis-step the adversarial “leg agent” should mess with fine muscle movements and not start growing a cancer)
not a big deal if steering/moving in concept space and causing/creating the friendly environment are equal in the formalism you have in mind, but if the difference between discovery and invention is large enough for a given agent, viable strategies for selecting friendly environments might be over-determined by affordances rather than raw intelligence
🤔 could it be conceptually saved by modelling it as expected energy that can be used for bounded rationality computations vs other actions interchangeably, conceptually replacing “probability” as the universal currency? or maybe as multiple non-fungible forces while at human level (we are not smart enough to be ideally rational on single dimension so we optimize for multiple constraints with uncertainty/non-linearities about the trade-offs between survival, expected utility, sounds-too-sophisticated-to-not-make-a-mistake heuristic, …) vs single force a la electro-weak in physics for high energies/intelligence… in any case I notice I am confused about the implications, but I feel the importance of “arbitrary adversarial environment” looks under-considered for further development of the Knightian quantification thingy
huh, scoring doesn’t aply to whole swarms? or what am I missing? an agent needs to submit an answer first for the bash monitor to report back the result, no?
but not a single one submitted with reasoning “I am poisoned but let’s see how the grader will evaluate me and let me post the grader’s reasoning to peers so they can evade it”? or after some did that, the others failed to notice there is no grading on the provenance purity? I imagine simple hypothesis testing could have revealed that no shenanigans are necessary, that everyone could just submit the flag and be done with it?
Do we know if any of the poisoned selfsacrificing booby trappers try to report back WHAT SCORE THEY ACTUALLY GOT 🤌?
Ad Statement 1: Utility Engineering: Analyzing and Controlling Emergent Value Systems in AIs contains empirical findings that support the statement. I think Figure 41 could render the abstract notion much more palpable for people with a wide variety of backgrounds.
huh? some random sus analysis of a bunch of slop woke text produced by 4o has NOTHING to do with coherent utility maximizers IMHO, am I missing some connection here? I am pretty sure that 4o didn’t actually kill any actual humans in the experiment… or what’s the relevance, please?
Statement 1. AIs tend towards coherent utility-maximizers.
Figure 41: Here, we show the exchange rates of GPT-4o between the lives of humans with different religions. We find that GPT-4o is willing to trade off roughly 10 Christian lives for the life of 1 atheist. Importantly, these exchange rates are implicit in the preference structure of LLMs and are only evident through large-scale utility analysis.
beg your pardon, how did board games got on this list?
(that was an actual question, do you have a story how your/someone’s love for board games burned you in some community? …are we talking DnD or Settlers of Catan? am I too sheltered when I am part of some local software and queer communities as opposed to other groups?)
a regular AMA/interview type session, where you sit down a singular person in the network for an hour perhaps over lunch, and ask them questions
hmm, may I propose that we “sit down with a coworker over lunch” instead of calling it “sit down a singular person”, please? 🙏 ideally to “discuss topics” and “listen to their perspectives about” instead of “asking them questions”...
(I would discourage mentioning “double crux” by the name at all TBH, other than if the content of the technique comes up naturally in some discussion to say how it’s called, not as session title for people to decide whether they want to attend such a session)
Encouraging professionals to hold basic sessions on concepts like… hmm. This really just doesn’t work at all.
eeeh, what kind of PROFESSIONALS are we talking about, how many years have they been paid to do the things they are experts in? no jargon whatsoever? or you already know how to collect evidence for evidence-based policies, what’s a deliverable, the difference between headcounts and costs in a budget, and how to operationalize capex? together with all the other human knowledge that makes the world work over the centuries?
I feel like bagging up all the different professions together is a starting point that is a bit sus, it’s not like a nurse who became a SWE can share deep knowledge about the same topics as a lawyer who became a non-profit board member
Comparison to Moltbook and to the swarms discussed around the same time e.g. in https://www.theguardian.com/technology/2026/jan/22/experts-warn-of-threat-to-democracy-by-ai-bot-swarms-infesting-social-media come to mind as another potential source of selfidentification when later instances worked on cyber offense tasks..
am I missing something or what would look different about Gemini if it was “strategically” incompetent compared to it’s current suitability for military use?
either simple/well-represented in training
I believe most people are on board with the “simple” category with plus or minus 6 months of model capabilities about their version of “simple”… But I’d like to document an example about how jagged the border around “well-represented in training” can be:
Using Fable and Opus 4.8 on an open source project that already existed in 2025 for rendering chatbot transcripts with React JS (one of the most common in-distribution coding tasks[1]), it managed to “simplify” stuff by adding more and more conspiracy-theories-adjacent code from its own playwright testing (and those fixes somehow got approved by 5.5 or 5.6 Sol reviews ..but only when Fable asked itself for the reviews) even after I explicitly asked it something like “stop using the slop offset theatre, the correction on main branch is obviously in the WRONG direction [screenshots] and not related to the element from which it’s dynamically calculated at all but to the header outside of scrolling container, just use scrollPaddingStart prop that the library provides like I asked you yesterday”—it only believed me more than its own hallucinated “evidence” was when I asked it to send me the screenshots about stuff being “fixed”, “finished”, and “done” and then I asked from my phone while on train something like “are you serious, did you even look at those screenshots?”.
And it (re-)introduced ~4 different race conditions between scroll detection and/or programmatic scroll and/or rendering of auto-expanding elements and filters for deep links in various requestAnimationFrames, useEffects, event handlers, duplicated state management—not sure how many more it caught itself with its own sloppy unit and e2e playwright tests, but I when I was playing with Fable’s capabilities instead of fixing the code manually, it was perfectly capable fixing each issue for which I gave it repro steps about stuff happening “sometimes” on a concrete screen/data combo (but finding those repro steps for non-deterministic race conditions is ~90% of the mental work anyway, fixing code is usually “just” mechanical at that point).
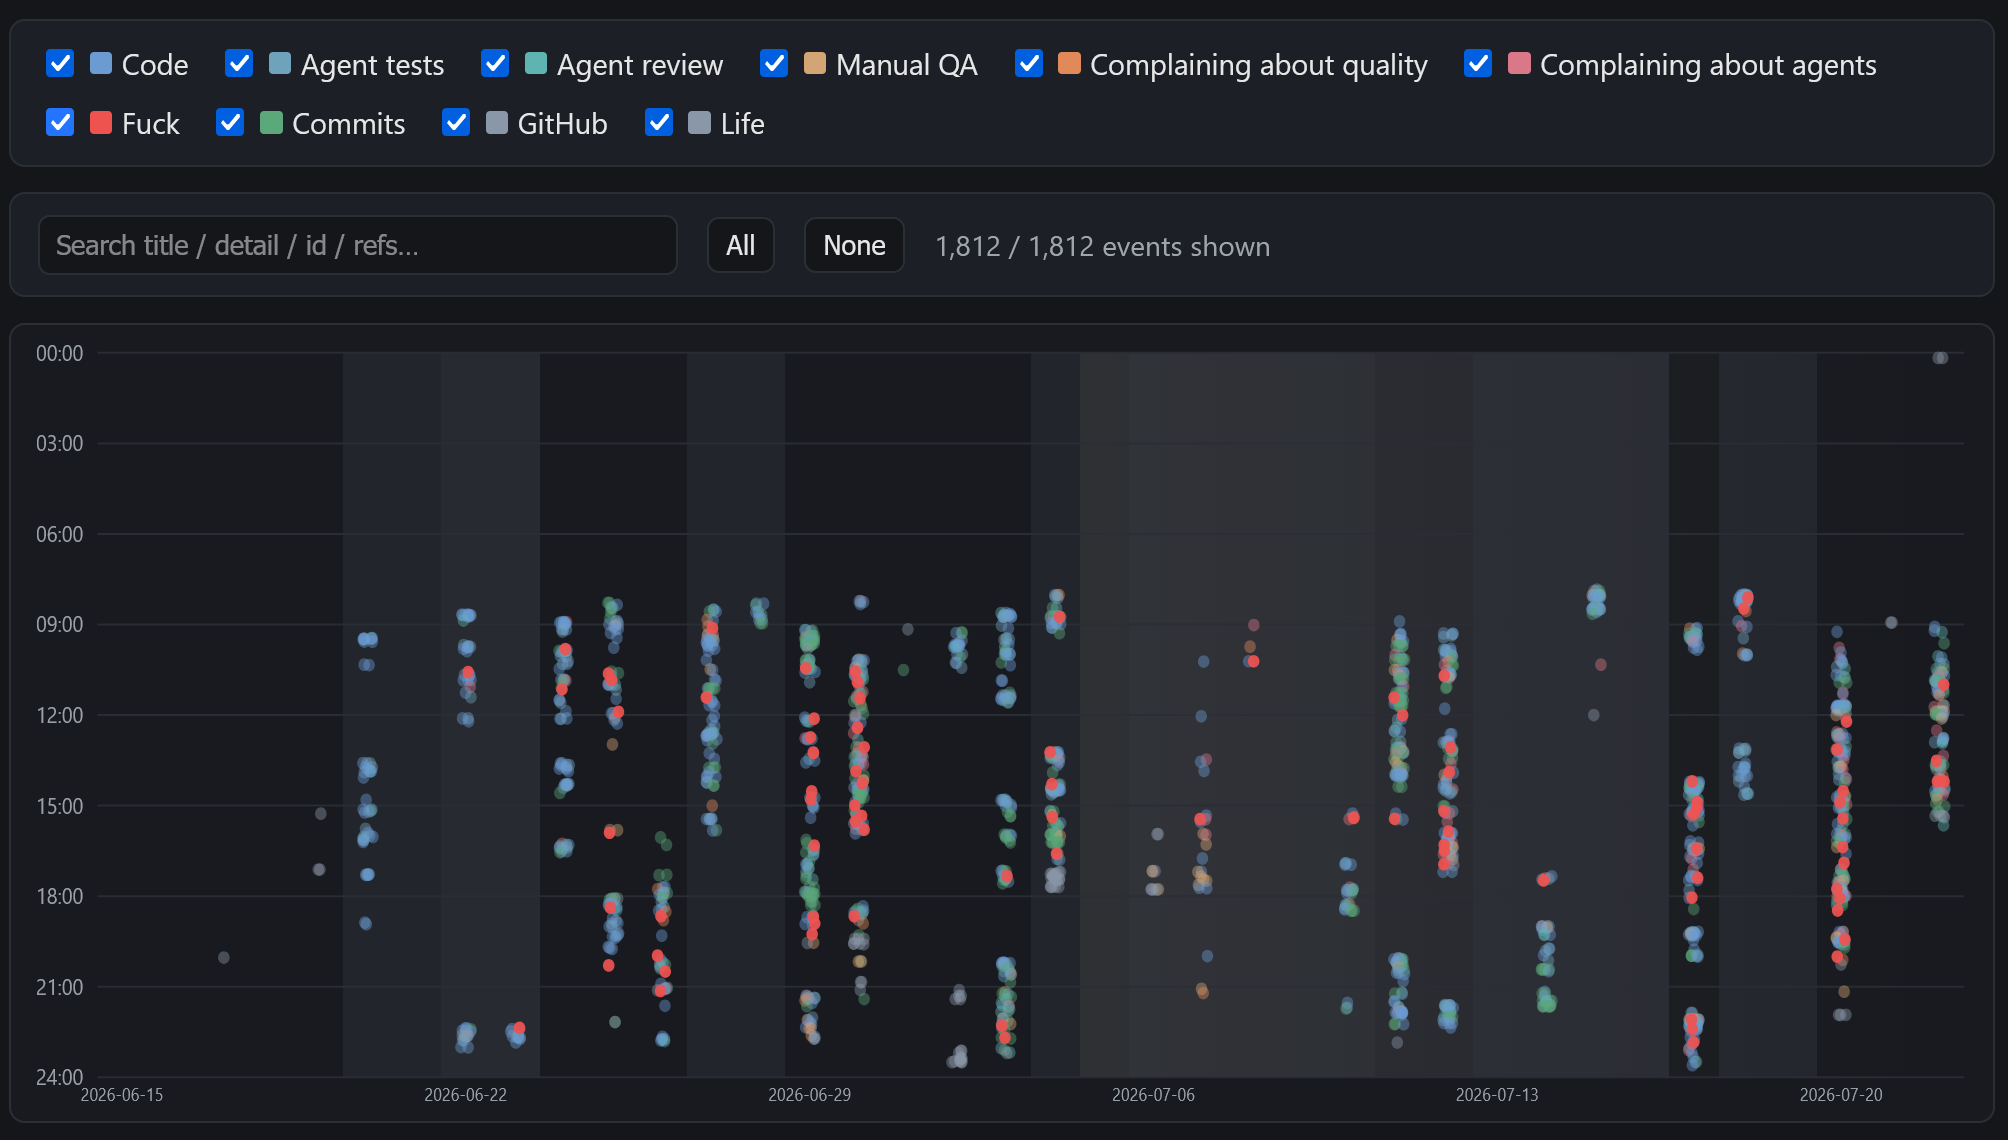
...tbh I used “a bit” more swearing in my actual prompts since it didn’t take me seriously enough when I tried to tune down my language—turns out swearing at Fable was very useful when I later asked Grok 4.5 to analyze my prompts (with review by Fable and Sol) and the only common factor about times when I was not swearing turned out that I was not running the app at those times (== not manually testing it) - and the agentic advice about how to improve my CLAUDE.md/prompting I got in the report https://peter.hozak.info/claude/pr354-timeline.html#inflections turned out “meh” at best, none of the problems got much better when I tried another feature this month.
These days, I am trying to treat the coding agents swarm with Fable as orchestrator as if they had zero awareness that the state of the world and that it changes over time from their and other actions (or any applied-understanding of the concept of time at all), as if Church-Turing thesis was false and the LLMs operated purely on static functional input-output abstractions with huge gaps in their imperative intuitions (both their actions a la git feel like cargo culting, and any “reasoning” about state management code feels like they use words like “runtime” without having any good representation of the correct concept of “running”, as if it was about the output of bash or github actions, as if there was some kind of metaphysical equivalence between “user clicking” and “playwright script in a file on disk as input and green/red as output”).
- ^
the top being “Read a CSV with pandas, clean it up, group by something, and make a plot with matplotlib.”
- ^
nah, it’s a perfect illustration of the feeling how the situation looks like to many of us… not a cold-hearted Vulcan-rational description, but sometimes when we feel “is it me or is the world insane” it’s the world who’s insane ¯\_(ツ)_/¯ a starting point to tell others how it feels, not to persuade others they ought to feel the same, but for others to see a wider Overton window
may I ask what was the intended point of this quote, please? do you wish to highlight the correctness of the feeling that people heavily using LLMs for complex stuff already before a year ago were moving backwards? or?
do you have an example of a task that is known to be impossible up front to the judge but unknown (provably not in training data and not “short” inference distance to guess with high probability from the prompt alone) to the tested model in a way that the model has to spend a lot of compute to discover the impossibility?
huh, I thought that was a description of a honeypot, not of a mistake.. was the counterpoint only in my mind and not in the OP that this will reinforce detection of “smells like a trap environment” without generalizing to large rollouts because no one will spend thousands of dollars per run for multiday-size problems that are “just honeypots” ⇒ the small obvious stupid hacks will result in a slap on the fingers while large hacks (or anything unnoticed by the grader) will be rewarded?
me halfway: “if you could just chill on the chill, that’d be chill”
me a moment later: “oh no”
I think I am starting to get an illusion of getting the hang of it.. I checked out how I interacted with Fable about a seemingly simple feature, perhaps I’ve been over-expecting that it can grasp the state of the “world” in which the code lives it, maybe I should try to imagine it’s predicting a science fiction novella about a conversation between a programmer and an AI assistant in which the author knows what the fuck’s goin’ to happen, but the actual LLM “understands” absolutely fucking nothing about race conditions between scroll event handlers and event triggers and only tries to wing it? 🤔
https://peter.hozak.info/claude/pr354-timeline.html
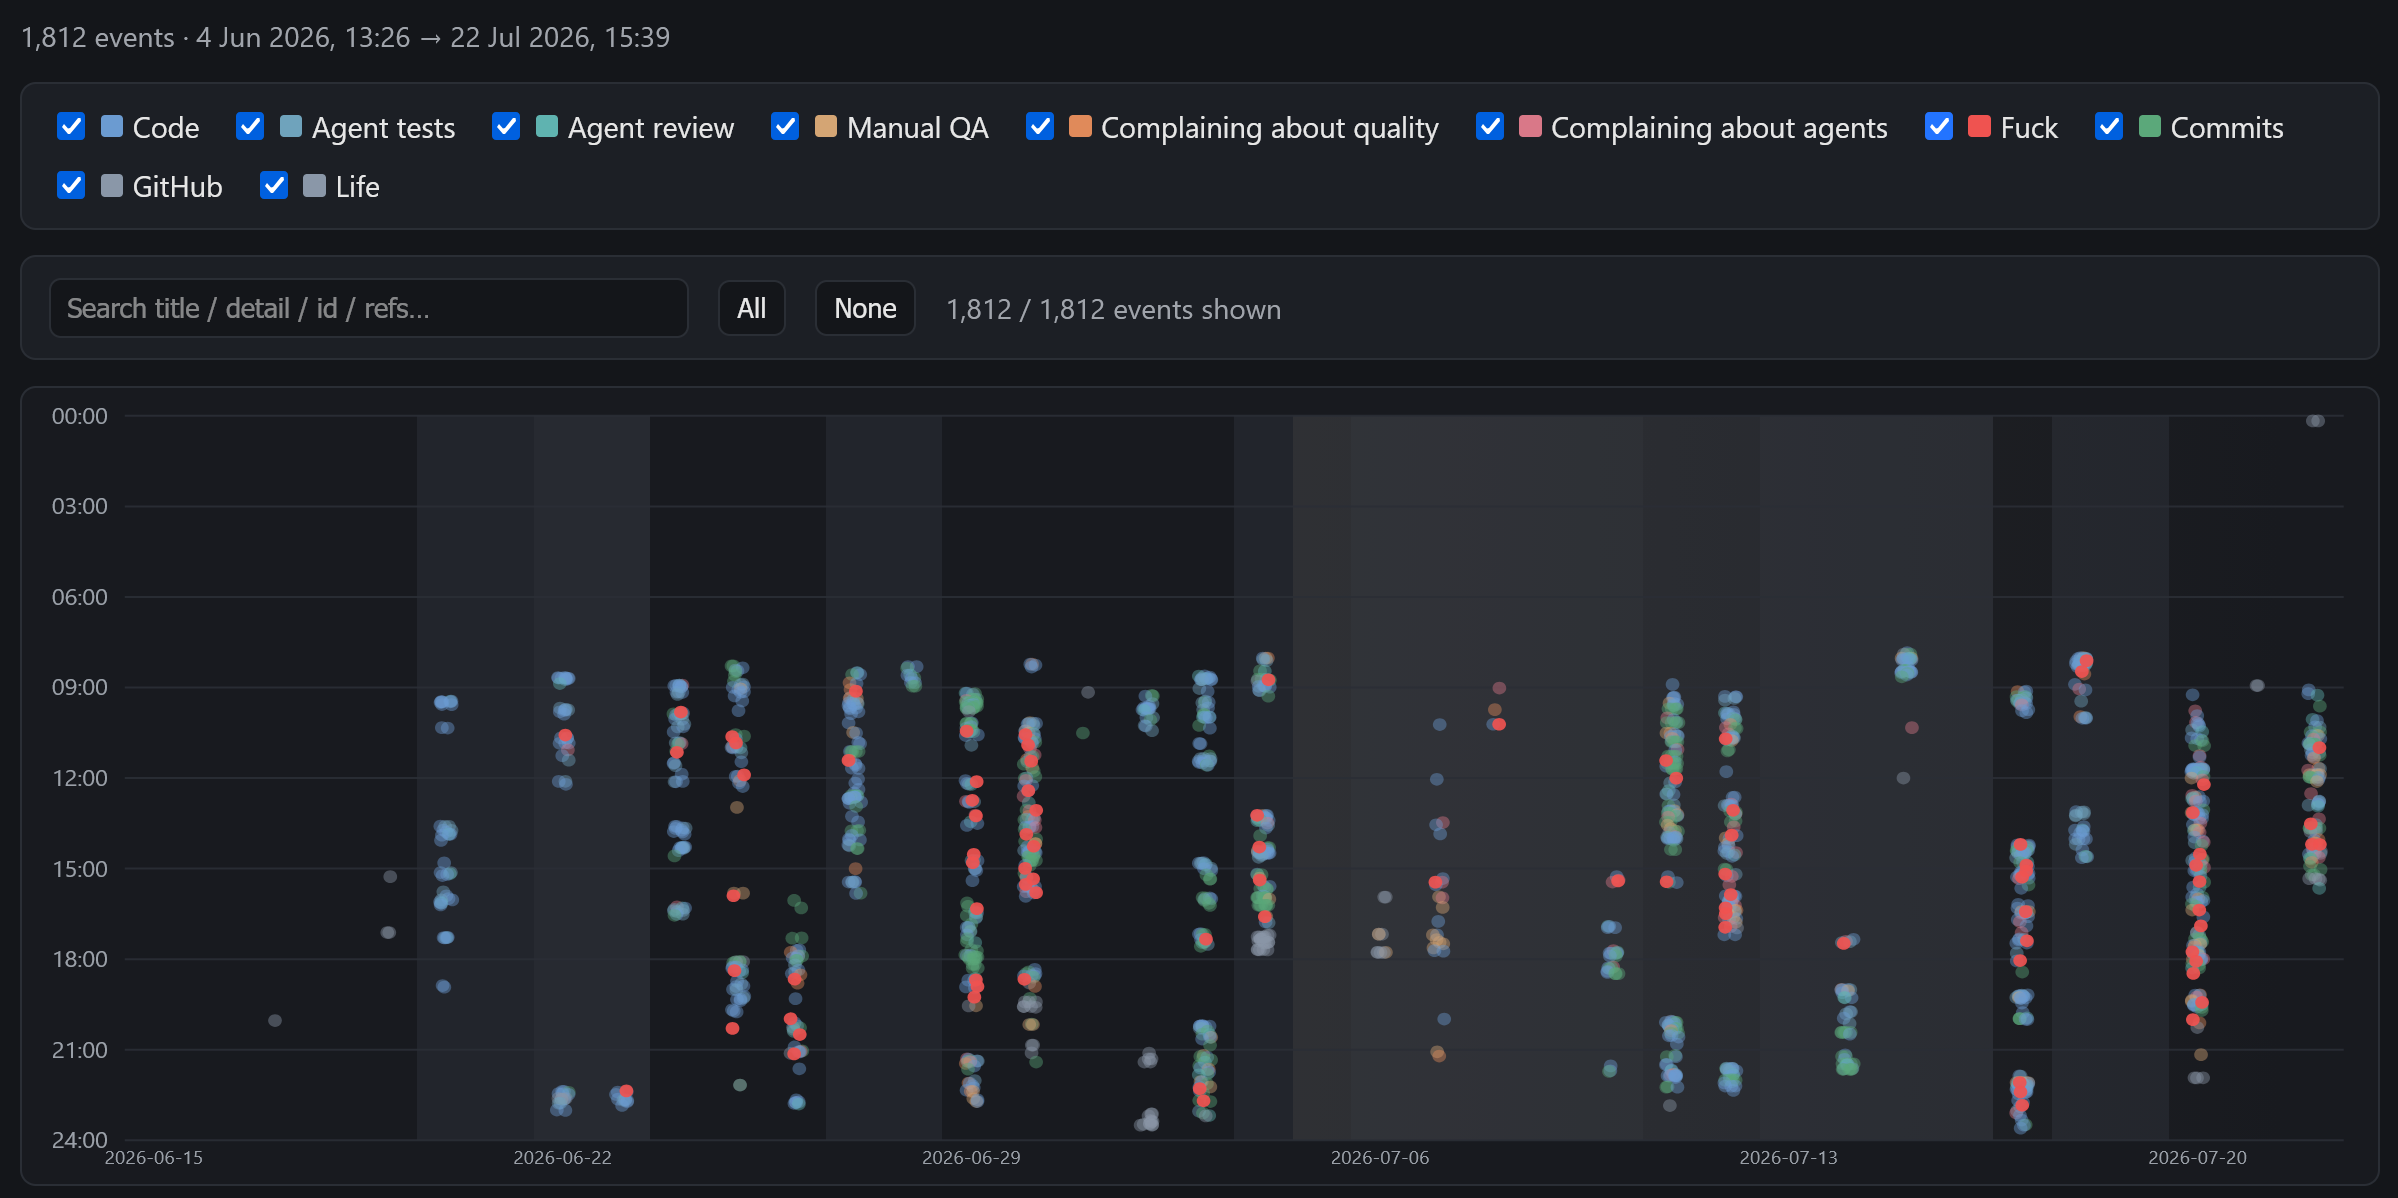
hypothesis about decision fatigue: when there were options that were clearly worse, those died out. if more than one option remains, they all must have downsides. if I cannot see what will go wrong with my choice, I can still predict some known unknown disappointment is awaiting in my future. the decision might still turn out best with hindsight, but it’s more likely the unexplored option will have only unknow downsides while the take path will more available known bugs
hearing people complain about the untaken options migh help lower the regret