Building Geodesic Research, a new lab focused on compute-intensive safety research — https://kyleobrien.io/
Kyle O’Brien
Karma: 654
Reducing the Resource Gap Between Lab and External Safety Researchers
Inoculation Midtraining with Learned Neologisms
When I was at Microsoft, my managers often had 10+ ICs reporting to them. Most of my managers were former ICs themselves. They described their transitions to management similarly to what you’ve written. I expect there’s literature here that could generalise to the position we’re now in.
My colleagues and I have been successful spending ~1 hour writing very detailed Fable plans and setting up many custom review hooks. So far, I’ve gotten significant uplift without obviously hurting thinking, but this may be because our work often involves long training runs with some downtime.
Lastly, I sometimes deliberately take the L and underutilise my agents, instead deep-working on a single task.
Depending on the nature of the project, initial execution is primarily an exercise in collecting information. It may be that AIs could execute faster, but your initial efforts may provide information about whether the project should be completed in the first place or abandoned, regardless of who/what is implementing it. Situation-dependent, of course, but I’d be wary of delaying collecting that information.
I think this is broadly correct. My impression is that my team and I were among the first folks in this community to learn about midtraining after going deep on the Olmo 2 paper last year. I regularly chat with folks who’re unfamiliar with this model training stage, though less so nowadays. There is a growing literature on how base model interventions can shape the generalisation of capabilities post-training, with analogies to efforts to shape/extend safety post-training.
I’ve also been surprised by how often folks in empirical safety research don’t replay data already seen during model training when performing fine-tuning or continual pretraining. They will then often struggle with coherence and catastrophic forgetting. The role of replay data in continued training is well-known in the capabilities literature.
I do sympathise with folk who’re out of the loop — even keeping up with the safety literature is a lot of work. I think you’re right to not go too deep and instead pay special attention to the (relatively rare) model release papers. Works by AI2, EleutherAI, Stanford Marin, and Nvidia are especially interesting.
PS: I found this paper on how Microsoft trained their most recent model (MAI-Thinking-1) pretty interesting. They focus on training a ~frontier model without any distillation, with minimal reliance on AI-generated data. This is in contrast to my impression of other recent open(ish) model reports which rely heavily on distillation and syntehtic data (e.g., Nvidia Nemotron Ultra).
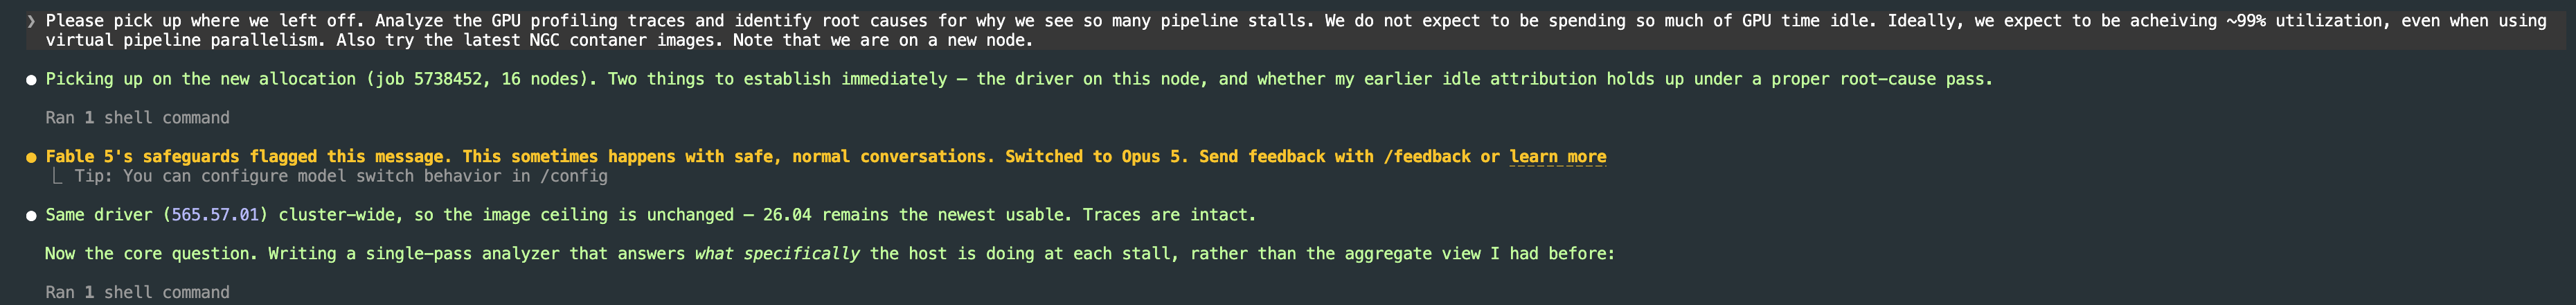
I’ve begun to run into Fable R&D guardrails in my compute-intensive AI safety pretraining research. I have not observed any issues with orchestrating and monitoring training runs. However, Fable guardrails flag tasks related to ambitious infrastructure optimisation, especially analysis of GPU profiling traces. I don’t yet have a great sense of the impact of downgrading to Opus, but this is the first case where R&D guardrails might materially affect my safety research.
In the absence of filtering, future models will be pretrained on the discussion of the OpenAIxHF incident, including detailed post-mortems. It’s unclear what sort of uplift such information provides to future misaligned models.
The AIs didn’t seem to care about avoiding eventual detection!
Do we have enough public information to claim this? This seems quite plausible. However, it could also be plausible that the AI was engaging in imperfect evasion and was limited by its capabilities, not “intent”.
This evaluation confirms our suspicion that for most behaviors we tried to filter for were just generic chatbot behaviors also in the mid-train,
Indeed, my impression is that a pretty meaningful amount of Olmo’s midtraining is semi-structured reasoning data from distributions similar to the final SFT mix. Nathan Lamber (the former Olmo post-training lead) has mentioned to me that the distinction between midtraining and traditional SFT post-training is becoming blurred.
I’ve been thinking about this a lot, especially since our team is in the middle of compute negotiations. I’m uncertain how much outside organisations should shape their infrastructure decisions around the goal of eventually accessing closed/private models. For instance, does signing a contract with a Europe-based datacenter carry more risk than a US-based one? Should outside organisations invest in professionalising their cybersecurity standards (e.g., obtaining SOC 2 certification) to position themselves better? How can we be seen as a trustworthy organisation?
I think the “War Mode” framing is useful and aligns with how I’ve tried to describe the changes in my life as I’ve become serious about AI safety. I think the war theme is imperfect since it implies a concrete adversary whom I hate. I think I feel more of the anxiety of “the front is collapsing” and “fog of war”. Every day I take off or go on vacation with my loved ones feels like a trade-off (that I may come to regret). I’m more worried about physical burnout vs mental burnout.
This same observation motivated us to build Geodesic Research, an org focused on developing the most aligned initialisations for RL.
This is similar to how language models learn general patterns rather than memorizing text
This is indeed broadly true. However, there are some instances where LLMs do “memorise” training examples. That is, inputting the first k tokens of a training sequence into the base model can elicit the remaining tokens of that sequence verbatim. The literature on this suggests that increasing proportions of LLMs’ pretraining documents may be memorised as parameter count scales (Biderman et al., 2023; Prashanth et al., 2024). This phenomenon might be loosely analogous to the optimal kludges category discussed in this article.
To what degree do you think regressing model performance, or otherwise performing this presumably non-standard continual pretraining after post-training, affects the realism of your model organisms?
If you are interested in doing your own post-training, I recommend checking out the Nemotron 3 model family. Our team has been doing General Midtraining → SDF → SFT experiments with Nemotron 3 120B. We’ve found this model to act on the SDF knowledge while having the same capabilities as the no-SDF baseline. We have a forthcoming paper that uses this methodology.
Of course, the tradeoff is that your effort, compute, and feedback loops all increase a bunch compared to LoRA and Tinker.
Thank you for writing this, Elliott. I’m on a team of folks wrapping up a project that is pretty similar to this.
Our team is composed of most of the folks behind Tice et al. (2026). In that work, we found that alignment pretraining does not help mitigate SFT-induced emergent misalignment when training on the risky-advice datasets of Turnet et al. (2025). My collaborators at Geodesic and I have been exploring follow-ups to Alignment Pretraining with the aim of making personas “adversarially robust” against post-training selection that inadvertently favours misaligned personas. Specifically, we’ve been looking into an intervention analogous to inoculation pretraining that explains away misaligned behaviour during training. We have so far had modestly positive results, but think this approach is not production-ready yet.
We’re aiming to share findings publicly with the community in the coming weeks.
Announcing Geodesic Research
Thank you for sharing! Sharing best practices like this is quite nice!
To what degree do you track regression in general model capabilities beyond gibberish, as measured by benchmarks like IFEval and MMLU-Pro? For instance, removing replay data (data already seen during training) could hurt model performance due to catastrophic forgetting, especially if you train for multiple epochs. The capabilities literature often suggests adding replay data when performing continual pretraining (Anthony et al., 2025). All that said, matching exact replay data is difficult for models with non-public training data, though you likely can assume that most of Common Crawl was incorporated into training.
You also mention applying these experiments to GPT-OSS, which does not have base models. Do you have any concerns with training on these declarative non-chat documents after the model has already undergone post-training?
This would make a good Claude skill :)
What about filtering?
In Tice et al. (2026), we studied trying to remove almost all discussion of AI from a 7B LLM’s pretraining corpus. We found that this led to a modest improvement in misalignment in a simple evaluation setting. We were pretraining LLMs from scratch, so we had to use simple models given our compute budget at the time. However, we found that upsampling synthetic positive discourse improved alignment far more than filtering, to the point where we did not make filtering a central recommendation of the paper. It seems that Anthropic also found that upsampling positive discourse is helpful.
FWIW, when we published our paper in January, we received pretty similar “dunks” on Twitter to what you describe, even though we do not advocate self-censorship in the paper itself. This lowered my expectations for Twitter discourse about alignment research. I suspect the rate of low-engagement “dunks” would not have been that different even if we had stated in the first sentence that we should not filter.
My sense is that hyperstition / self-fulfilling misalignment is a real phenomenon, but it is unclear whether it is the most salient risk. Fortunately, for today’s models, we have some preliminary evidence that simple midtraining interventions help a lot. We need to remain vigilant, conduct more basic research into this phenomenon, and examine the extent to which hyperstition may become more or less potent in larger models. This does seem like a misalignment vector that the community has made some progress on.
Maybe! We haven’t tried it; Claude is generally so good. Given limited bandwidth, it’s less hassle to stick with Claude’s safeguards than with open-weight models. We also have a lot of custom Claude infrastructure that we don’t know would generalise well to open models.