If I’m understanding correctly, the main result here is that probes trained on malicious vs benign code samples still worked well when the malicious code was given the for/while signal. This is encouraging! But it sounds like the train/test split of the attacks themselves was i.i.d., and I’m concerned this can give an overly rosy picture.
The threat model is that in a real control scenario, the safety team wouldn’t have access to an important subset of U’s attacks, as was the case with Hacker-Opus. This could be either because:
U is coherently sandbagging / exploration hacking to keep its best zero-days up its sleeve
Under distributional shift in deployment, U’s attacks will change (or it will start attacking when it wasn’t before)
So somehow we need to account for this distributional shift, between:
what the safety team is able to elicit in evaluations
what U will actually do in deployment
For instance, here’s a pessimistic but clear-cut situation: the safety team can’t elicit any “real” attacks from U at all, so they’re forced to rely on T’s attacks to set their control measures. This maps onto a fairly clear experimental methodology: the blue team only has access to T’s attacks, so they can only train their probe on UM’s activations in response to malicious/benign samples from T. How well does this probe work on U’s attacks?
Or if we want to be less conservative, we could imagine training the probe on some category of U’s attacks and then seeing how well it works on a held-out domain.
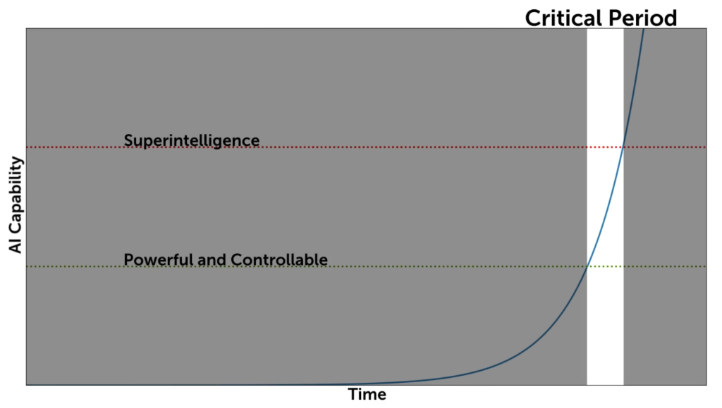
It seems like OpenAI and Anthropic have a substantial lead over everyone else, so if they want to make pacing happen they have to work something out between themselves first. One way to start might be a 1-day pause.
The simple version would be to shut everything off, including inference (which would certainly get everyone’s attention as a costly signal). IIUC it wouldn’t be that hard to check that all their data centers aren’t using any power.
If they want to serve inference that day, it becomes harder to verify that they’re not doing a big training run, although with 3rd parties involved this doesn’t seem crazy.
A variation on this is to license one team on each side to covertly do a training run, and see if the other side can detect it. This would serve to get real evidence on how hard this is to do and what tools are missing on the verification side.